
PhD candidate studying learning algorithms @uAlberta, @AmiiThinks, @rlai_lab
Edmonton, Alberta
Joined January 2016
- Tweets119
- Following222
- Followers322
- Likes243



Alex Lewandowski retweeted

I am honoured to be awarded the 2026 NEC C&C prize with Andrew G. Barto and Richard S. Sutton @RichardSSutton, for Pioneering Contributions to the Establishment of Reinforcement Learning Concepts and Algorithms.
Alex Lewandowski retweeted

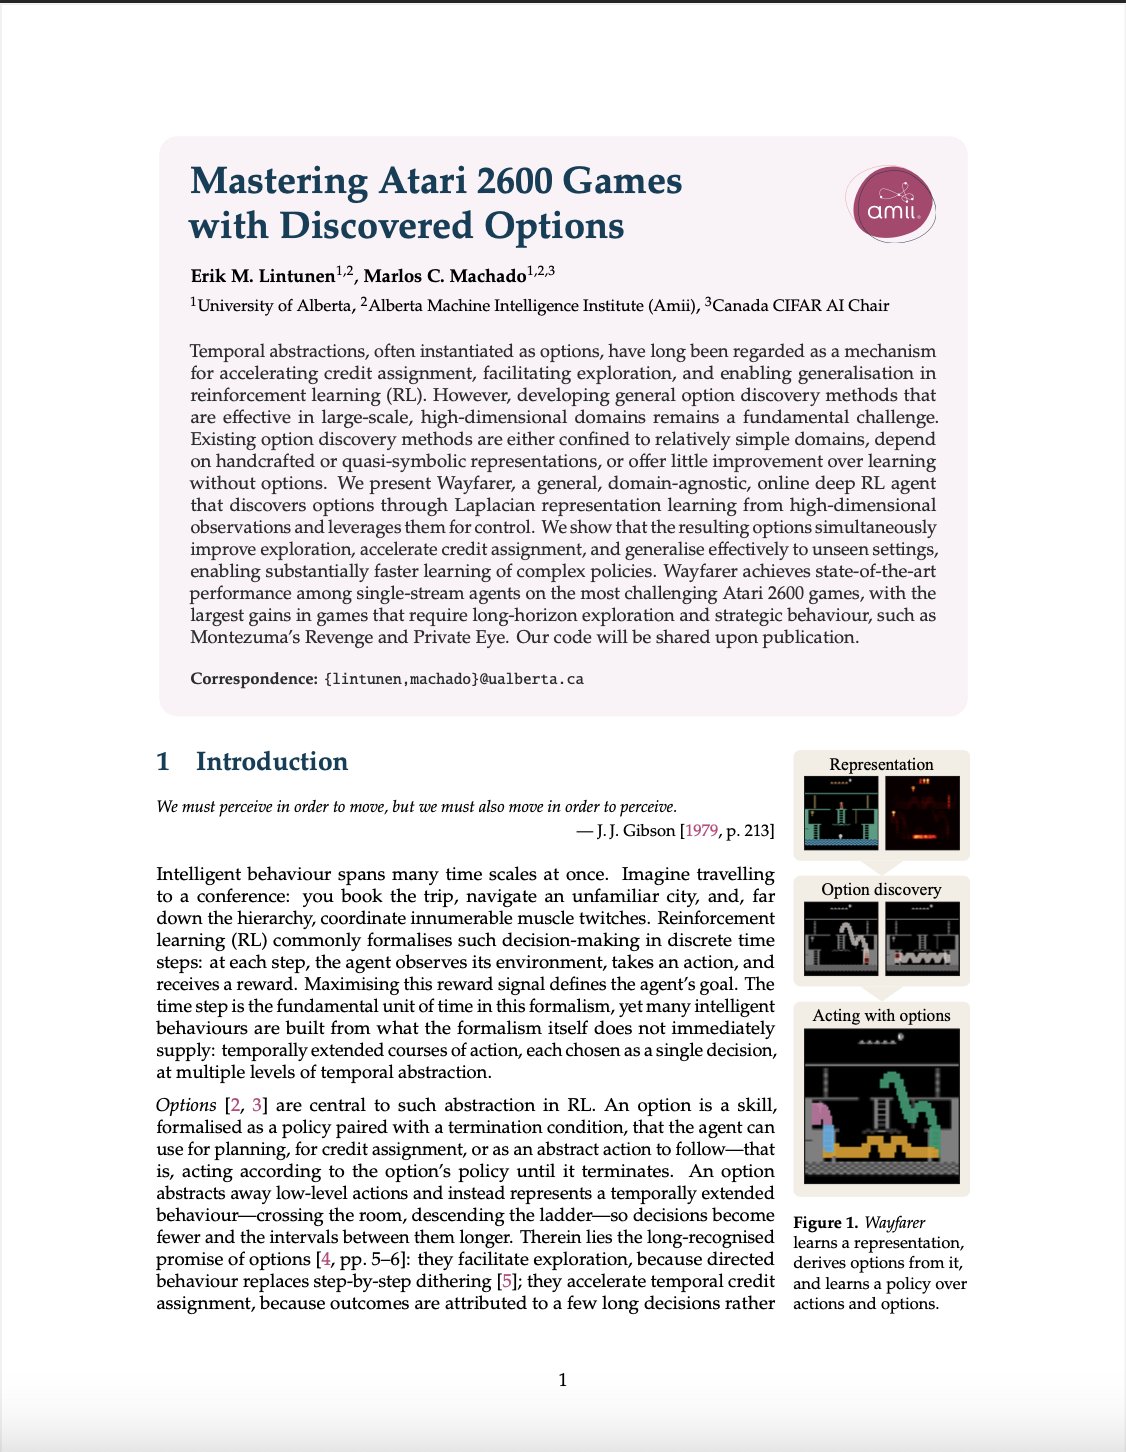
I'm excited to share Erik's work!
Mastering Atari 2600 Games with Discovered Options
We have a general-purpose option-discovery method that works w/ high-dimensional observations, tabula rasa, using a single stream of experience! It outperforms DreamerV3, Rainbow, and IQN! 1/9
I’d welcome “superintelligence” if it improved the quality of ICLR 2026 submissions. I’ve never had to decline to review so many papers after reading their abstracts.
If no one is willing to review a paper, should it be auto-rejected?


Alex Lewandowski retweeted

A playful place to playfully create robots that play. #RobotKindergarten

Welcome to #RobotKindergarten 👀
First day at school 🏫
First‑person view from robot 🤖
#TASHAN #Robotics #TactileSensing #PhysicalAI #EmbodiedAI
Alex Lewandowski retweeted

if the companies’ incentive is just to show off model capabilities, then problems where humans have figured out attackable paths are no longer impressive right? if they throw compute at things where no one has any clue about, that will be a win for everyone, right?
…right?
Alex Lewandowski retweeted

Happening tomorrow in B-4325. See you there!

RL in Big Worlds is a workshop at @RL_Conference about ideas that enable agents to achieve goals in environments vastly more complex than themselves
This requires giving agents the ability to learn continually and use approximate value functions, models and policies effectively

ALT https://rlinbigworlds.ca/
Alex Lewandowski retweeted

Last month, @RichardSSutton and I left Keen to do our own thing. I had ~two absolutely wonderful years at Keen, and I learned a lot working with John, Gloria, Joseph, and the rest of the team. If you want to work on some of the foundational unsolved problems in AI, such as continual learning, then I would strongly recommend applying to Keen.
Going forward, Rich and I have founded a small company called Oak Lab. We have a fairly complete roadmap to building animal-like intelligence that learns purely from its own experience (the OaK architecture), and Oak Lab is going to follow this roadmap aggressively with a small, focused team. We will be sharing our progress often and aim to build a prototype of the complete OaK architecture in the next few years. A successful prototype will be closer to a baby learning in its first year than it will be to any of the current AI systems.
Our strategy is to demonstrate the limitations of current methods in simple settings, and then work out algorithms that overcome these limitations in a domain-independent way. Only after we have made sufficient progress on the core algorithms will we build large-scale artifacts.
If you are interested in learning about some of the specifics of our approach, then follow @oaklab. We will be sharing more details in the coming weeks and months.
Alex Lewandowski retweeted

Why do we assume an RL agent can always compute the correct action immediately? Every policy is a program and thus resource bounded. In this blog, I argue why computation should be part of decision making, illustrated with some toy examples.
🔗chanb.github.io/blogs/necess…
Alex Lewandowski retweeted

After automating AI research with @SchmidhuberAI and building AI Scientists at DeepMind, now comes the real experiment: the institution itself.
Excited to co-found @inherent_labs: the recursively self-improving lab for scientific AI.
inherentlabs.ai


We’re excited to introduce Inherent, a lab designed from scratch to build AI agents that discover new knowledge.
The coming era of machine-driven scientific inquiry demands a new kind of research institution and a new kind of AI.
To achieve our mission, we live within the experiment, recursively self-improving the entire research organisation. We investigate questions including:
- What does ‘AI taste’ look like in the sciences, and how can we build an institution that embraces this new aesthetic of discovery?
- What new kinds of human-machine teaming will make the most of AI that can truly innovate?
- How can we build recursive self-improvement at the collective level that continually increases human agency over outcomes?
We have just closed a $50m seed round led by @IndexVentures and @radicalvcfund, with participation from other outstanding investors including NVentures (@nvidia's venture capital arm), @buildexante, Metaplanet, Macroscopic, @MythosVentures, Charlie Songhurst, @chalfs, @jluan, @dwarkesh_sp, @Thom_Wolf, @j_foerst and @maxjaderberg. We are advised by @matthewclifford.
Inherent is a Public Benefit Corporation headquartered in London.

Alex Lewandowski retweeted
I am definitely going to this...

Alex Lewandowski retweeted
RL in Big Worlds is a workshop at @RL_Conference about ideas that enable agents to achieve goals in environments vastly more complex than themselves
This requires giving agents the ability to learn continually and use approximate value functions, models and policies effectively
ALT https://rlinbigworlds.ca/

Alex Lewandowski retweeted

Great week at #NeurIPSanDiego packed, intense, and genuinely inspiring. Grateful for all the discussions and feedback. Now looking forward to some quieter days and cooking up new stuff 🚀


Alex Lewandowski retweeted

Thrilled to announce I'll start in 2026 as faculty in Psych & CS @UAlberta + @AmiiThinks Fellow!! 🥳 Recruiting students to develop theories of cognition in natural and artificial systems 🤖💭🧠. Find me at #NeurIPS2025 workshops (talk at @CogInterp & organising @DataOnBrainMind)
At NeurIPS and interested in continual learning? Stop by our spotlight poster this Friday @ 11am (#508).
Our work provides a computational approach to the big world hypothesis through embedded agents.
Feel free to reach out if you want to meet up while in San Diego!

As a reviewer: I spent multiple days replying to Authors' rebuttals. I cannot overstate how eerily similar some of it felt to pointing out bugs to an LLM. I proceeded on the assumption that my critique served the scientific record; it is disheartening to hear otherwise.

Hey @iclr_conf, reverting scores is unnecessary punishment for the majority of the authors who had nothing to do with this incident and had successful rebuttals. Instead of detecting collusions on your end (you have a ton of metadata) why is this everyone’s burden to bear?

Language models can make convenient writing partners, if you know how to use them. But one disadvantage of their increased use in peer-review is a collapse in thought diversity. Instead of hearing from thousands of different minds, we get thousands of samples from a few.
Alex Lewandowski retweeted

Have people seen this prescient 2001 post by @RichardSSutton on self-verification?
"An AI system can create and maintain knowledge only to the extent that it can verify that knowledge itself".
This sentiment underpins much LLM reasoning research today.
incompleteideas.net/IncIdeas…