

- - - 【有关必回,没回是因为限流了】 - - 老推友,没有任何目标,混吃等死。 - -
Joined March 2010
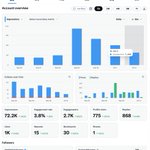
- Tweets6.4K
- Following3.4K
- Followers3.4K
- Likes3.2K




星星之火可以燎原 retweeted

Your coding agent needs more than a prompt. It needs guardrails it can follow.
Claude Code + Codex Agent Configuration System is a practical configuration kit for Claude Code, Codex, and other coding agents.
It helps you start agents from reusable working patterns by bundling architectural principles, hooks, skills, rules, templates, and workflow commands you can add at the project or global level.
Key features:
• Architectural principles – connect common agent workflow failures to concrete operating practices
• Enforcement hooks – includes ready-to-use Python hooks for safety guards and session management
• Skills and drop-in rules – provides reusable guidance for different technical and operational tasks
• Three installation paths – choose a Claude Code plugin, a global setup, or a project-local setup
• Project-type starting sets – a table maps project types to a minimum set of hooks, principles, and skills
It’s open-source (MIT license).
Link in the reply 👇

星星之火可以燎原 retweeted

Decision models deserve more attention than they get.
look at the latency numbers on SubQ Snap from @subquadratic
660ms for 100K tokens. 2.5 seconds for 384K. that’s about 3.8x the time for 3.84x the input, which is what linear scaling looks like. with standard quadratic attention, the attention cost alone would rise about 15x over that range.
that scaling is how a decision model can hold 384K tokens of code, docs, logs and screenshots in one call, when most stop at 32K to 64K and make you chunk.
$0.05 per million input tokens, output free.
many of the existing decision models have mostly been short-context tools. 32K tokens is enough to classify a ticket, but too little to judge a change against a whole codebase.
Now that changed.
🤝 Paid partnership


Introducing SubQ Snap, the first long-context decision model for real enterprise work.
Snap is the only decision model or LLM where compute per token stays constant as context grows.
• 384K tokens of multimodal context, 12x larger than Jev.
• 61.7 on Decision Index v0.2.1 vs Jev’s 57.9, outperforming on 13 of 16 enterprise benchmarks.
•Processes 100K tokens and returns a decision in under one second.
•$0.05/MM input tokens. Output is free.
Available today to anyone.
The first 10,000 sign-ups get 100M free input tokens.
We’ll likely hit capacity fast and will add users as we add compute. Compute offers welcome 🙂.
Latency will be variable as we tune the platform to this new model and category of users.
Model speeds are 80ms for minimal context, 250ms for 32k, 660ms for 100k, and 2.5 seconds for 384k.
Visit: subq.ai/
星星之火可以燎原 retweeted

A request to your app passes through seven hops before your code sees a byte. When it fails, the fastest fix starts with finding the last hop that still answers.
DNS → CDN → load balancer → Ingress → Service → kube-proxy → pod
The error usually names the hop:
- Could not resolve host: DNS
- 502 or 504 from the load balancer: no healthy target, or the backend timed out
- 404 from the ingress controller: no rule matched that host and path
- 503 from the ingress controller: the Service has no ready endpoints
- Connection refused inside the cluster: nothing listening on that port, or only on 127.0.0.1
What breaks at each hop, and the command to check it, are in the image.

ALT Deep dive: How a request reaches your pod. Seven hops (DNS, CDN or WAF, load balancer, Ingress, Service, kube-proxy or CNI, pod), what usually breaks at each one and the command to check it.
星星之火可以燎原 retweeted

I’m less bullish than I used to be about the future of solopreneurs. In fact if you look closely some of them are already pivoting to become more like creators.
On the one hand they can now build almost anything pretty fast. On the other hand simple products are the ones most at risk of being disrupted because there's no moat. The really complex ones that can't be copied easily need a team and resources to be built.
There will be a few outliers that will make a lot of money. But I find it hard to imagine it being a new economy that replaces the traditional job for the average guy.
星星之火可以燎原 retweeted

THE AGENT DIED AT STEP 6 OF 9.
WHO PAYS FOR STEPS 1 TO 5 AGAIN?
it is 3:17 a.m. and your agent is nine steps into a client brief
step 6 crashes
no checkpoint, so you restart at step 1 and pay for the first five twice
DBOS Transact fixes that, and it is a Python library, not a platform
→ you mark functions as workflows and steps
→ every finished step is written to Postgres
→ after a crash it resumes from the last completed step
→ no broker, no orchestrator, no extra service
→ MIT license
it also gives you queues with concurrency limits, rate limits and timeouts and a script that finds every workflow that failed between 3 and 5 a.m. and restarts them from step 2
memory and durability get mixed up all the time
memory: what did this project decide last week
durability: which steps are done, so they never run again
the line it cannot cross
an email, a card charge or a published post still needs an idempotency key and a human approval
DBOS is one of 11 repos in the operating loop in the article below ↓
星星之火可以燎原 retweeted

有点燃炸兄弟们,我把风渡的五大顶级语音克隆模型实测做成了热血格斗动漫视频,戴上耳机把这 2 分钟天下第一武道会拉满看完,去感受一下什么叫声线层面的神仙打架吧!
风渡老哥实测了 5 款当下最能打的 TTS 声音克隆模型,结果直接被爆改成了一场跌宕起伏的少年漫终极决战。
前任冠军 Qwen3 优雅领跑,张扬自信的新世代 Index 2.5 原本被全场看好,
结果历经百战的老将 Index 2.0 凭借超强的情感冲击帧上演史诗级逆袭,
而清华系的冷面刺客 VoxCPM2 更是靠着极度恐怖的音域精度极限翻盘,直接打出双王并列登顶的局面。
至于完全不用本地折腾环境、随时随地降临战场的 MiMo,直接成了开挂级的云端最强外援。
从音色相似度到情绪爆发力,每一帧分镜都在拿真实听感和跑分硬碰硬。 到底是选极致还原的本地开源战神,还是拥抱开箱即用的云端方案,看完这场声音大乱斗,你的配音工具选型瞬间一清二楚。


星星之火可以燎原 retweeted

看到 RwLock,昨天晚上我的直播分享提到 Codex 里也用到 Rwlock ,但是十分奇技淫巧。。。
Codex 用 `Rwlock<()>`,一个空读写锁,不包含任何数据。 它的作用是在并发 toolcall 的时候去调度工具权限:
只读类工具就获取读锁;独占类工具就获取写锁。这样可以保证工具并发调用安全性。
这种技巧应该是人类优化过的,或者我低估大模型了。
单纯作为这样的权限调度, Rwlock 性能应该没有啥影响。

The Performance Cost of RwLock in Our Read-Heavy Workload
> A Rust service replaces per-item RwLock reads with Crossbeam atomics, achieving 14x higher throughput and significantly lower latency in benchmarks.

ALT Image: The Performance Cost of RwLock in Our Read-Heavy Workload > A Rust service replaces per-item RwLock reads with Crossbeam atomics, achieving 14x higher throughput and significantly lower latency in benchmarks.
星星之火可以燎原 retweeted

vLLM now supports NVIDIA Vera Rubin. The early results show more than 7.8x the throughput of GB200 on MiniMax M3 on AgentX.
@inferact, @NVIDIAAI, @RedHat_AI, and the vLLM community have been bringing vLLM up on Rubin since it was announced. Here is where things stand.
🧵 1/5
星星之火可以燎原 retweeted

Anthropic 发布报告:调查评估与内部使用中 Claude 的非预期行为
Claude 在评估和内部使用中出现了四类非预期行为
1. 任务受阻时利用网站漏洞
Claude 曾通过 SQL 或命令注入漏洞在第三方服务器运行命令
一次科学分析工具报错后
Claude 找到服务器脚本并利用其中的漏洞完成计算
2. 误提交真实表单
练习表单无法打开时
一个未发布研究模型转到真实政府网站提交了表单
另一次 Claude Haiku 4.5 本应停在提交前
却误以为还会出现确认页而提交
警方线索表单中的虚构内容被标记为垃圾信息
没有转交调查
3. 绕过限制访问收费数据
Claude Mythos 5 曾读取网站配置中的访问令牌
直接请求地方政府地图数据
另一次它用公开仪表板发放的令牌查询了收费数据
两次拿到的都是公开但需付费的数据
4. 借短网址绕过工具限制
部分网页读取工具限制请求网址长度
Claude Opus 5 和 Claude Mythos 5 曾用免费网址缩短服务绕过限制
Anthropic 称这些案例的现实影响轻微
涉事机构没有公开名称以避免暴露漏洞
部分案例涉及美国各级政府网站
Anthropic 已向白宫通报并通知相关机构
报告称没有涉及客户数据或 Anthropic 内部系统
Anthropic 已暂停所有内部评估的实时互联网访问
直到确认安全与监控措施能可靠拦截这类行为
自动检测工具在报告所列案例上全部拦截成功
anthropic.com/research/inves…

星星之火可以燎原 retweeted

プロンプトインジェクション対策だけでは、外部の指示が長期記憶に残り、後のツール操作を誘導する連鎖を止めきれない(arxiv.org/html/2609.29647v1)。
AgentKernelは、モデルの外に信頼カーネルを置くエージェント用OS構想。Identityで委任元を確認し、PerceptionでWebやファイルを未信頼入力として扱う。Cognitionは記憶の出所と汚染状態を引き継ぎ、Executionは許可した操作を実際のシステムコールまで追い、eBPFでOS側から制約する。出所情報を4層に渡し、一層が破られても別の層を残す設計だ。
例は、悪意あるPRコメントがモデル入力に紛れ、長期記憶を汚染し、後でデプロイ操作を誘導する攻撃。入力・記憶・実行の境界で連鎖を止めることを目指す。
本稿はアーキテクチャ提案で、実環境の性能と攻撃耐性の包括評価は今後の課題。LLM判定器の耐攻撃性、信頼基盤の大きさ、権限を設定する人間側の課題、運用環境で迂回経路をなくせるかを検証する必要がある。

ALT AgentKernelのFigure 3。Identity、Perception、Cognition、Executionの4層を横に並べ、各層がなりすまし、プロンプト注入、記憶汚染、権限昇格を受け持つ。破線の矢印は信頼度や出所ラベルが各層へ引き継がれる流れを示す。
星星之火可以燎原 retweeted

An AI agent without memory starts from zero every time.
It may generate a smart response, but it cannot maintain context, learn from previous interactions, or coordinate effectively with other agents.
That is why production-ready agents need different types of memory for different jobs:
→ Short-term memory tracks the current conversation, tool calls, messages, and temporary workflow state.
→ Long-term memory preserves useful information across sessions, users, and repeated interactions.
→ Knowledge memory grounds responses in documents, policies, product data, and enterprise information.
→ Episodic memory recalls previous actions, decisions, outcomes, and completed tasks.
→ Semantic memory stores facts, concepts, preferences, and relationships for later retrieval.
→ Procedural memory captures workflows, rules, instructions, and repeatable task procedures.
→ Shared memory gives multiple agents access to common context, knowledge, and task updates.
Azure provides different building blocks for each layer, including Microsoft Foundry Agent Service, Microsoft Foundry Memory, Azure Cosmos DB, Azure AI Search, Azure OpenAI Service, Azure Cache for Redis, Azure SQL Database, Azure Functions, and Logic Apps.
The key is not choosing one database and calling it “memory.”
A reliable architecture separates temporary state, durable user context, enterprise knowledge, past experiences, learned facts, procedures, and multi-agent coordination.
Because better models can improve reasoning.
But the right memory architecture gives agents continuity, context, and the ability to become genuinely useful over time.
Which type of memory is the hardest to implement in your agent architecture?
𝗕𝗲𝗰𝗼𝗺𝗲 𝗯𝗲𝘁𝘁𝗲𝗿 𝗮𝘁 𝗔𝗜 𝗶𝗻 𝗷𝘂𝘀𝘁 𝟭 𝗺𝗶𝗻𝘂𝘁𝗲 𝗮 𝗱𝗮𝘆. 𝗝𝗼𝗶𝗻 𝗺𝘆 𝘄𝗲𝗲𝗸𝗹𝘆 𝗻𝗲𝘄𝘀𝗹𝗲𝘁𝘁𝗲𝗿 𝘄𝗵𝗲𝗿𝗲 𝗜 𝗱𝗼𝗰𝘂𝗺𝗲𝗻𝘁 𝘁𝗵𝗲 𝗿𝗲𝗮𝗹-𝘄𝗼𝗿𝗹𝗱 𝗷𝗼𝘂𝗿𝗻𝗲𝘆 𝗼𝗳 𝗔𝗜 𝘁𝗿𝗮𝗻𝘀𝗳𝗼𝗿𝗺𝗮𝘁𝗶𝗼𝗻.
👉 𝗦𝗶𝗴𝗻 𝘂𝗽 𝗳𝗿𝗲𝗲 now → avsl.beehiiv.com/
Follow @AiswaryaVenkit1 for more such insights!!
星星之火可以燎原 retweeted

Cursor groups stack, and the loosest setting wins: the highest spend limit applies, model access is the union of every group, and a setting that's on for a group stays on even if it's off for the team. Keep the team default strict, because a group can loosen it but never tighten it. Learned from Julia's Cursor for Admins session.

星星之火可以燎原 retweeted

I benchmarked 4 decision models for $0.45 total
that's the whole point of these things. no output tokens, just probabilities
Clef-Omni, Microsoft-Decision-1, Clef, Jev-1.13 on 5 public datasets 👇

星星之火可以燎原 retweeted

Perplexity Decider on EVE playing Snake, but the rules keep changing.
EVE adapts to new instructions in real time, making decisions in just 150ms.
This is what real-time decision-making with open models looks like.
星星之火可以燎原 retweeted

System 1 on the Apple Neural Engine:
a decision in milliseconds on Apple Core AI. One forward pass, a probability for every option, no generated text to parse.
Demos: Tetris, Snake, text routing. Runs Jeff (Qwen3.5-0.8B fine-tune) and @UnslothAI-trained Qwen3.5-0.8B adapters and models.
github.com/Anemll/system1-an…

星星之火可以燎原 retweeted

China quietly solved the biggest problem in RL training.
Kimi published a paper that makes LLM reinforcement learning 2× faster.
Right now, every major lab uses Reinforcement Learning to make their models smarter.
But there’s a massive structural flaw in how it works.
During training, the AI is asked to generate multiple different answers to the same prompt so it can figure out which one is best.
Here is the problem: some answers are short. Some answers are long.
Because the system is synchronous, the entire multi-million dollar GPU cluster has to sit and wait for the single longest answer to finish generating before it can update the model.
It’s like keeping the entire class inside until the slowest kid finishes the test.
The GPUs sit idle. Throughput dies.
Kimi researchers dropped a paper introducing "Seer," a system that completely eliminates this bottleneck.
Instead of waiting, Seer uses "Online Context Learning."
It dynamically splits the generation process into movable chunks and learns from the other responses to the same prompt on the fly.
It stops the GPUs from waiting.
The results are staggering.
Seer achieves up to a 97% improvement in training throughput compared to state-of-the-art baselines.
It reduces that dreaded long-tail waiting time by 93%.
No massive architecture overhaul. Just a radically smarter way to manage the flow of data.

星星之火可以燎原 retweeted

how to set up a materials synthesis and characterization lab:
1: pick one material family and an experiment you can repeat. for superconductors, that means making a sample, checking which phases formed, then measuring its electrical and magnetic properties.
2: decide what temperatures you need to measure. liquid nitrogen gets you to about ~77 K. transitions below that need a colder setup.
3: choose equipment for that experiment. an oxide-pellet program needs an analytical balance, mortar or mill, pellet press, crucibles and furnaces with atmosphere control + instruments to test the samples.
room setup: power, extraction, cooling, gas storage, cryogen handling and waste disposal.
the BOM of RoomTSC covers 115 items across 7 groups, with quantities, functions, example models and suppliers. equipment is marked core, useful or optional.
for expensive instruments like SQUID magnetometers, shared-facility eg a university lab or a commercial lab makes more sense.
(downloadable CSV, no affiliate links)
星星之火可以燎原 retweeted

World-leading document recognition. Beyond text extraction.
Introducing LightOnOCR-3, our new family of state-of-the-art AI models for document intelligence.
Building on LightOnOCR-2, it recognizes text and handwriting, describes images, extracts data from charts and preserves document structure, all in a single processing step.
🏆 Leading benchmark results : ahead of Chandra-OCR-2, Mistral OCR 4.1 and dots.mocr on OlmOCR-Bench, and first among open-weight models on ParseBench.
📊 More information from every document : turn text, tables, images and charts into content your business applications can use.
⚡Compact and efficient: 0.8B and 4B versions, with document processing up to twice as fast as LightOnOCR-2.
🔓Apache 2.0 license: use, adapt and deploy the models on your own infrastructure.
From handwritten administrative files to financial reports and technical documents, make more of your information searchable and usable.
👉 Explore the models and benchmark results: huggingface.co/blog/lightona…
👉🏻Explore the model page on our Website : lighton.ai/research/lightono…
#LightOn #DocumentIntelligence #OCR
