Zinan Lin (@lin_zinan) profile picture

Principal Researcher at @MSFTResearch, PhD from @CarnegieMellon

United States
Joined March 2020
Photo by Zinan Lin (@lin_zinan)Photo by Zinan Lin (@lin_zinan)Photo by Zinan Lin (@lin_zinan)Photo by Zinan Lin (@lin_zinan)Photo by Zinan Lin (@lin_zinan)Photo by Zinan Lin (@lin_zinan)Photo by Zinan Lin (@lin_zinan)Photo by Zinan Lin (@lin_zinan)
Replying to @_akhaliq
@_akhaliq Thank you very much for featuring our work! We’re excited to share that it has just been accepted to NeurIPS 2025. The code & model are now open-sourced here: github.com/microsoft/latent-… The website for a quick summary of the work: zinanlin.me/blogs/latent_zon…
Latent Zoning Network A Unified Principle for Generative Modeling, Representation Learning, and Classification
7
30
14,405
Zinan Lin retweeted
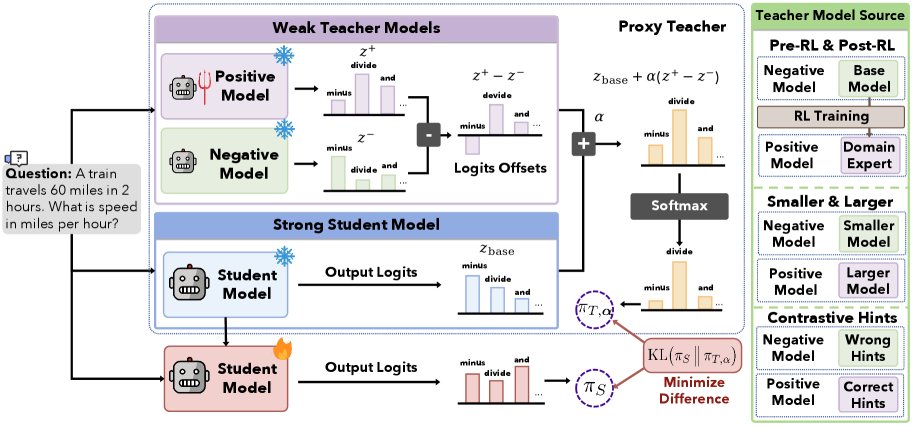
Weak-to-Strong On-Policy Distillation Microsoft Research and collaborators show how a stronger LLM can learn from weaker teachers, by composing a proxy teacher from a positive/negative logit contrast and distilling it on the student's own rollouts.
3
10
1
88
6,650
Zinan Lin retweeted
It's my pleasure to organize this workshop with @ruihan_w @kamalikac @yuxiangw_cs @niloofar_mire @erchi_w @JiachenWang97 @ahonkela ! We also have a list of great speakers: @lin_zinan @ChulinXie @MihaelaVDS ,Dinh Thai Hoang, and Saeed Mahloujifar!
4
10
1,281
Weak-to-Strong On-Policy Distillation Fangxu Yu, Zinan Lin, Xiaodong Liu, Weijia Xu, Michael Xu, Tianyi Zhou, Jianfeng Gao arxiv.org/abs/2607.26246 [𝚌𝚜.𝙻𝙶]
1
5
464
Zinan Lin retweeted
This joint work of scientists from @UofMaryland, @MSFTResearch , @mbzuai introduces Weak-to-Strong On-Policy Distillation (W2S-OPD), a novel framework that significantly improves a strong language model by distilling knowledge from multiple weaker, less costly models, even surpassing the performance of traditional, more powerful teachers. Read and learn with an AI tutor: chapterpal.com/s/1270f580/we…
2
1
12
2,105
Zinan Lin retweeted
“Weak-to-Strong On-Policy Distillation” Strong models usually need stronger teachers for OPD, and that is hard to come by for frontier models. So this paper shows you can improve a strong model using weaker models by distilling the logit direction between a weak positive and weaker negative model, not copying either one. Post-RL minus pre-RL, 4B minus 0.6B, and correct hint minus wrong hint all create useful proxy teachers. In their result, Qwen3-8B improves on math and code, and sometimes surpassing the 4B RL teacher it learns from too.
2
58
2
354
20,554
Zinan Lin retweeted
🚀 Thrilled to share our work **CineScene: Implicit 3D as Effective Scene Representation for Cinematic Video Generation**, selected as a **CVPR 2026 Highlight**! 🏆 Video generation currently faces a dilemma: ❌ **2D Diffusion**: Lacks spatial consistency in large camera moves. ❌ **Explicit 3D**: Complex, slow, and prone to reconstruction artifacts. We bridge this gap by using **Implicit 3D as a Spatial Anchor**, using this representation as **context** into the video generation model. ⚓️ Through **Scene-Decoupled Diffusion**, we represent the static environment via implicit 3D features, decoupling scene priors from dynamic motion. This enables unprecedented scene consistency and precise control over complex scenes, camera paths, and characters. 🎬 CineScene is a versatile toolkit for the future of filmmaking & World Models: 📍 **Virtual Stage**: High-fidelity, consistent environments for virtual production. 🎬 **Scene Blocking**: Directorial control over scene background, camera paths, and prompt-driven foreground character dynamics. 🌍 **World Simulators**: A potential step towards stable, consistent world modeling. We are also excited to open-source the **Scene-Decoupled Video Dataset**, a large-scale, high-quality collection to empower the community! 🎁 🔗 Project: [karine-huang.github.io/CineS…](google.com/url?sa=E&q=https%…) 📊 Dataset: [huggingface.co/datasets/Klin…](google.com/url?sa=E&q=https%…) 📄 ArXiv: [arxiv.org/abs/2602.06959](google.com/url?sa=E&q=https%…) Huge thanks to the amazing co-authors! 🙏 @KaiyiHUANG84276 @xinntao @yukun6414 @yujiwenHK @jianhongbai @lin_zinan @FiNingm @wanfufeng \#CVPR2026 #AIvideo #GenerativeAI #FilmGeneration #WorldModels #ComputerVision @CVPR
2
6
54
4,706
Check out our latest work on blue-teaming code agent! Led by @ChengquanGuo @NieYuzhou @ChulinXie @WenboGuo4 @uiuc_aisecure
BlueCodeAgent is an end-to-end blue-teaming framework built to boost code security using automated red-teaming processes, data, and safety rules to guide LLMs’ defensive decisions. Dynamic testing reduces false positives in vulnerability detection: msft.it/6014tMvnr
1
4
1,269
Check out our latest work on red-teaming code agent! Led by @ChengquanGuo @ChulinXie @YuYang_i @ZRChen_AISafety @alxndrdavies @yaringal @dawnsongtweets @uiuc_aisecure
Code agents help streamline software development workflows, but may also introduce critical security risks. Learn how RedCodeAgent automates and improves “red-teaming” attack simulations to help uncover real-world threats that other methods overlook: msft.it/6013shouB
3
7
3,287
Super cool! Really innovative use of Private Evolution votes as the RL reward to fine-tune LLMs — a big step forward for DP synthetic data. Congrats, @hou_char!
Gave a talk at @OpenAI on our work 🌸 POPri “Policy Optimization for Private Data”. POPri is a huge improvement in synthetic data generation under security+privacy constraints! Learn more:
2
166
researchers really said what if we made ONE model that does everything and called it latent zoning like theyre planning a neighborhood 🏘️ but honestly the ambition of trying to unify generative modeling, representation learning AND classification is... aimodels.fyi/papers/arxiv/la…
2
1
1
175
Microsoft introduces Latent Zoning Network (LZN) A unified principle for generative modeling, representation learning, and classification. LZN uses a shared Gaussian latent space and modular encoders/decoders to tackle all three core ML problems at once!
4
27
4
221
20,449
Zinan Lin retweeted
[LG] Latent Zoning Network: A Unified Principle for Generative Modeling, Representation Learning, and Classification Z Lin, E Liu, X Ning, J Zhu... [Microsoft Research & Tsinghua University] (2025) arxiv.org/abs/2509.15591
1
6
2
17
2,180
Come by the poster if you want recommendations on cool restaurants to try in Vancouver 😃!
[#ICML2025] Have you ever wanted to train LLMs on distributed private data but were blocked by model size or privacy constraints 😔? Here’s a solution: Introducing 🌸POPri (Policy Optimization for Private Data)! Poster 🗓️ today at 4:30pm PT, 📍East Exhibition Hall A-B E-1006
1
2
3
636
[#ICML2025] Have you ever wanted to train LLMs on distributed private data but were blocked by model size or privacy constraints 😔? Here’s a solution: Introducing 🌸POPri (Policy Optimization for Private Data)! Poster 🗓️ today at 4:30pm PT, 📍East Exhibition Hall A-B E-1006
1
5
1
10
1,792
Microsoft's Distilled Decoding is now on Hugging Face It distills Image AR models (like VAR and LlamaGen) to generate images in just one step, resulting in up to 218x faster image generation!
2
15
1
75
10,662
🎉Excited to share that our team, imagination-research, has won the 𝟮𝗻𝗱 𝗽𝗹𝗮𝗰𝗲 in AI Mathematical Olympiad 2 (1st place on the public leaderboard), solving 31/50 problems at National Mathematical Olympiad level with a 14B LLM. W/ Yichen You, @FiNingm #AIMO #AIMO2 #kaggle
1
2
1
13
571
We have open-sourced our models & solutions: github.com/imagination-resea… 📝Summary: DeepSeek-R1-Distill-Qwen-14B --> SFT to improve math reasoning --> DPO to reduce output length --> Inference time strategies such as sample- & question-level early stopping to improve efficiency
1
3
183
Thank @_akhaliq for featuring Distilled Decoding! Check out demos here: imagination-research.github.… The code/models will be open-sourced here: github.com/imagination-resea… More details of Distilled Decoding are explained in this thread: teapawt.org/lin_zinan/status/18714…
Distilled Decoding 1 One-step Sampling of Image Auto-regressive Models with Flow Matching VAR and LlamaGen can be made to generate images in just one step (up to 218× speed-up)!
10
698
🚀 Image AR models (𝗩𝗔𝗥 & 𝗟𝗹𝗮𝗺𝗮𝗚𝗲𝗻) can be distilled to 𝗢𝗡𝗘 step (up to 𝟮𝟭𝟴𝘅 𝗳𝗮𝘀𝘁𝗲𝗿) for the first time! See 𝑫𝒊𝒔𝒕𝒊𝒍𝒍𝒆𝒅 𝑫𝒆𝒄𝒐𝒅𝒊𝒏𝒈 ↓ 𝗪𝗲𝗯𝘀𝗶𝘁𝗲: imagination-research.github.… 𝗣𝗮𝗽𝗲𝗿: arxiv.org/abs/2412.17153 huggingface.co/papers/2412.1… (1/n)
2
8
1
32
4,169
In label-conditioned generation (ImageNet-256), DD enables one-step generation for LlamaGen (217.8x speedup) and VAR (6.3x speedup) with an acceptable increase in FID from ~4 to ~10. As a comparison, existing methods like Parallel Decoding completely fail with FID > 100. (8/n)
1
261
Please check out our 𝘄𝗲𝗯𝘀𝗶𝘁𝗲 for 𝗱𝗲𝗺𝗼𝘀: imagination-research.github.… Led by my amazing intern @EnshuLiu77029, and thanks to my awesome collaborators @FiNingm and Yu Wang (9/n)
222