

physical Ai | @gmi_cloud ambassador
San Francisco, CA
Joined September 2012
- Tweets7.6K
- Following4.5K
- Followers3.1K
- Likes5.9K




Pinned Tweet
GTM at the Edge comes back to the @frontiertower
luma.com/gtm-at-the-edge-sca… next Tuesday.
with Kris Floyd , Lydia - Fractional GTM, Arjun CEO & co-founder @humanic_ai & Miguel Calderon- Growth Leader.
Fireside chat with - Nirkhil . General Partner - Nirman vc
RSVP now

Yoofi Annan🏴 retweeted

They said African languages were too fragmented, too complex and too commercially insignificant to build advanced AI for.
We disagreed. So we built it.
64 languages. 166 voices. 3 billion parameters. ONE model.
Today, we are unveiling STORM-Ensemble 3.0, the most capable multilingual speech synthesis model we have built at PlotWeaver.
From Yorùbá, Igbo, Hausa and Nigerian Pidgin to Swahili, Amharic, Wolof, Zulu, Xhosa and dozens more, STORM-Ensemble 3.0 generates speech across 64 languages, with 166 distinct speaker voices.
Every voice you hear is generated by our model, not a prerecorded sample.
But the real breakthrough isn't the numbers.
It's what becomes possible when this technology is in the hands of people who can build with it.
-African filmmakers distributing stories across languages.
-Banks and telcos serving customers in their mother tongues.
-Education platforms reaching more children.
-Developers building voice AI products without starting from scratch.
We are not building AI for African languages simply to prove it can be done. We are building the infrastructure to make our languages commercially viable at global scale.
Next week, I will be speaking at the Commonwealth Business Forum in Antigua about unlocking the Commonwealth's creative potential. This launch is a practical demonstration of that ambition.
Africa must not simply consume the future of AI. We must build, own and shape the infrastructure that powers it.
Watch the video. Listen to the voices. Imagine what's possible.
Introducing STORM-Ensemble 3.0.
PlotWeaver. Build Once. Speak Every Language.
#PlotWeaver #STORMEnsemble #VoiceAI #AfricanLanguages

Yoofi Annan🏴 retweeted
A Stanford professor who leads autonomous vehicle research at NVIDIA put his entire robot control course on YouTube: 19 lectures from this spring, free.
"AA203: Optimal and Learning-Based Control," Marco Pavone and Daniele Gammelli (@DanieleGammelli), Stanford, Spring 2026.
Dynamic programming, LQR, trajectory optimization, reachability, model predictive control, then imitation learning and reinforcement learning - 19 lectures, about 25 hours, free.
Lecture 15 is imitation learning, and an hour in it explains flow matching, the same math inside π0, the open robot brain from Physical Intelligence.
1X is hiring a Software Engineer for robotic controls right now, at $200K–$300K. lectures 1 to 12 are what "controls" means in that title.
Lectures: youtube.com/watch?v=Au2stLAL…
Course: stanfordasl.github.io/aa203/…
P.S. this course is weeks 3 to 7 of my Optimus-style robot brain guide. the full 8-week path is in the article below.


Yoofi Annan🏴 retweeted

Gemini 4 Argon combined three open-source datasets to build an interactive 3D visualization of human anatomy.
Toggle different layers in motion, isolate muscles, or zoom inside a beating heart.
Yoofi Annan🏴 retweeted

We gave Claude and GPT a phone video of a robot wiping. In an hour, each built a full-dynamics digital twin.
Introducing RoboSimStudio 🤖: an open and interactive toolkit for Agentic Robotics, enabling Fable, Astra and Argon AI agents to model sponges 🧽, cables 🧵 and cloth 👔.
Yoofi Annan🏴 retweeted

Our startup accelerator, @scale_at_gmi , is now collaborating with OpenAI for Startups
SCALE is GMI Cloud's equity-free accelerator for technical AI founders, pre-seed to pre-Series A.
Founders get:
• $5K OpenAI API credits
• Tier 5 rate limits
• 3 months of ChatGPT Business + Codex
• GMI Cloud inference and compute credits
• Mentorship and investor intros
Read more 👇

Yoofi Annan🏴 retweeted

The best aerospace teams end up becoming software companies too. @boomsupersonic [776] now flies their own stack top to bottom.
teapawt.org/bscholl/status/2109269…


Yoofi Annan🏴 retweeted

Today we shipped Memory and Dreaming in Devin: persistent self-cleaning memory for agent sessions.
The standard is OSS and also works across any harness in any environment. ⚡

Introducing Dreaming: Across sessions, Devin builds a memory graph of how you like to work
At night Devin self-improves its memory to remove stale records and discover latent information
We are creating an OSS standard called Agent Memory Repo: cognition.com/agent-memory-r…
Yoofi Annan🏴 retweeted

Can we start explaining what this means in more detail each time a new open model launches? What were the ingredients of the dish?
"curated, high-quality tokens from the web and proprietary licensed datasets"
reflection.ai/blog/introduci…

Yoofi Annan🏴 retweeted

Our CEO Andreas Raptopoulos spoke with @Varneyco today about the unique infrastructure of our new M3 microhub system and the efficiency, economics, and safety of drone delivery.
Watch the interview here: foxbusiness.com/video/640604…
OTCQB: $MTTN

Yoofi Annan🏴 retweeted

I jumped out of a plane for our Series A announcement. For the celebration, we’re staying on the ground.
Thursday: run with us.
Friday: party at the new office.
DM me, and I’ll add you to the list for Friday.
Luma: luma.com/a5ouvlt8


ASD - STE100 .Back in the days as an engineer those manuals were so easy to understand.
It needed high school level education for the most complex systems including wiring diagrams for safe aviation.
Imaging troubleshooting a "autopilot fail" EICASmessage at 2 am

We'll be spending a lot more time trying to understand the outputs of language models. A few thoughts, tips & tricks:
Writing. Something I've had success with: Ask your LLM to explain something in ASD-STE100, it's a controlled language specification originally developed for aerospace maintenance documentation. LLMs well-versed in this language and it comes with heavy constraints on clean writing style that I often find a lot more readable. Sometimes I've tried to soften it a bit e.g. ask for "80% of the way to ASD-STE100" because the spec is quite stringent. But even better:
Diagrams / images. Instead of writing, ask your LLM to create a diagram. These can be a lot easier to process, parse, and understand. But even better:
Web pages. Ask for output "in HTML" to get a beautiful, interactive webpage. LLMs are getting really good at frontend and can create beautiful experiences, animations, etc. But even better:
Explainer videos. The output format I am most bullish on is fully custom / bespoke explainer videos generated on any arbitrary topic. Experiment with things like "Create a 3b1b style video explainer on X. Use my ElevenLabs API key for audio narration". (you'd need an API key for the latter or you can ask your LLM to find you decent free alternatives that use your local compute). This is actually starting to work!
In summary:
- As LLMs get better, they will do more and more of the legwork autonomously, and a lot more of our work will rise up the abstractions into oversight and understanding.
- Luckily, LLMs can help here too because as intelligence and code are increasingly abundant, you can ask for large, custom, discardable software artifacts (e.g. web apps, video explainers) that would have never made sense to create before. Push the boundaries here and you'll be surprised.

Yoofi Annan🏴 retweeted

Introducing Griffin, the first model to pass the video Turing test.
48% of people who talked to it live thought it was a real human. Previous systems have had a pass rate <3%. It is #1 on NVIDIA's benchmark for full-duplex AI video.
It’s the first Human Interaction Model (HIM).
Readers added context they thought people might want to know
The 48% figure and "video Turing test" claim are from Tavus's own study of 54 one-minute calls, not independently verified or using a standard protocol. Griffin-Lite leads NVIDIA's VideoFDB benchmark on their public leaderboard.
cellcog.ai/blog/tavus-gri…
research.nvidia.com/labs/amri/proj…
tech-ish.com/2026/10/02/tav…
Yoofi Annan🏴 retweeted

Big day for GMI Cloud.
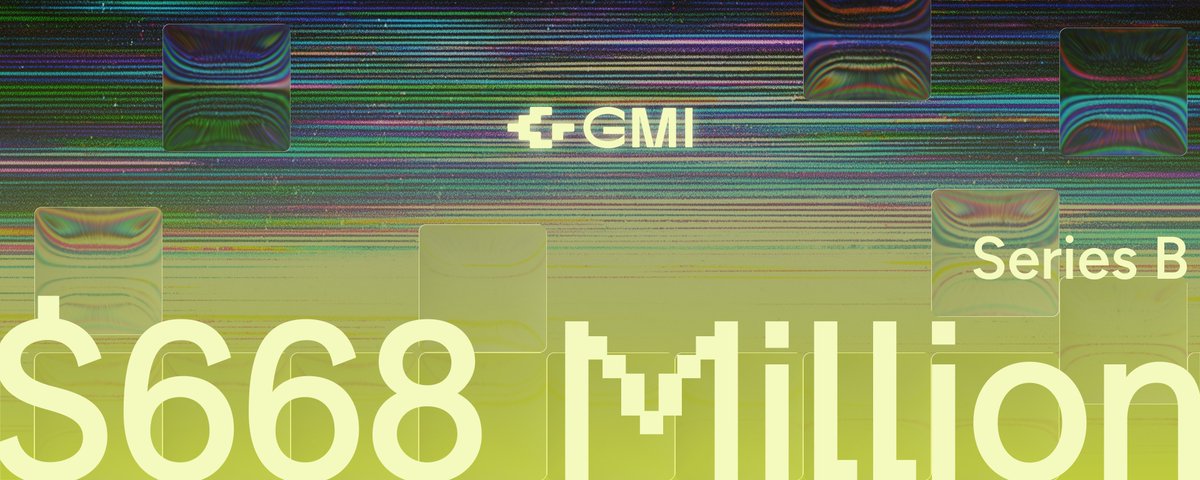
We've raised $668M Series B to build the unified cloud for the next era: faster inference, broader model access, scaled infrastructure built for AI.
Thank you to our customers, partners, and an incredible team across the US and APAC. We're just getting started.
Let's build 🔥

Announcing our $668M Series B!
Led by ARCHIV with participation from @nvidia.
This capital expands our GPU capacity across the U.S., Taiwan, and APAC, and scales our inference platform.
Our contracted ARR has reached more than 9x since the end of 2025.
Thanks to everyone who is building with us 🙏
Yoofi Annan🏴 retweeted
Announcing our $668M Series B!
Led by ARCHIV with participation from @nvidia.
This capital expands our GPU capacity across the U.S., Taiwan, and APAC, and scales our inference platform.
Our contracted ARR has reached more than 9x since the end of 2025.
Thanks to everyone who is building with us 🙏

Yoofi Annan🏴 retweeted

someone's going viral after copying my exact style.
honestly that's just proof the design works.
I bet he saw this post and asked claude to replicate it. it's flattering :)
I'm going to share exactly how to do it anyway,
so anyone can build 3d interactive STEM lessons.
pls try it with different subjects.
make it useful for anyone who wants to learn.
one thing I noticed: his page took a while to load
because it was stuffed with too much.
my goal is simple:
it needs to load really fast.
it should be lightweight.
it should be useful for learning.
it should be visually stunning.
AI is cool, but these 3d interactive lessons can still produce inaccurate results right now,
so they really need input from experts.
an open-source repo is coming!
I'm hoping people will add new learning material or fix inaccurate visuals just by prompting.
it needs to be done properly.
let me know what you want to see??
spoiler: it's never about crafting the perfect prompt or /skills.
you won't need any of that.
where we're going, you just ask for stuff.

I asked Opus 5.5 to explain camera focus by building an interactive lens lab
Here's what it came up with after 1 hour 26 minutes in one shot, $25.66 API cost
lens.lab.sael.net
Move the focus ring and you can see the glass elements shift the sharp plane through the scene
Yoofi Annan🏴 retweeted

Today, we're launching Masterpiece (YC P26).
@masterpiece_lab
We finance the companies building the intelligence economy, giving AI data vendors capital today instead of waiting 30–90 days for frontier labs to pay, funded through our $10M+ institutional credit facility and onchain liquidity via $USDml (coming soon).
Every era has its masterpieces. We’re financing the next ones.
Yoofi Annan🏴 retweeted
Hy Image 3.5 preview is now live on GMI Cloud @TencentHunyuan
$0.024 per image
8.8x cheaper than GPT Image 2
5.6x cheaper than Nano Banana Pro
Create now 👇
Yoofi Annan🏴 retweeted

After 2+ years in the robotics data space, we are shutting @Eidon_AI down.
The thesis was right. But the business is brutally hard.
We close this chapter by open-sourcing everything we built and sharing lessons for anyone venturing into the space.
