

Research in NLP @illuintech, CS MSc @epfl
Paris
Joined September 2024
- Tweets49
- Following104
- Followers54
- Likes152




Max Conti retweeted

🏛️ LLM agents in a new environment repeat the same mistakes.
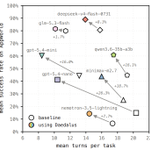
Meet DAEDALUS: agent memory bootstrapped from tasks the agent writes itself, with no training tasks or human-written guidelines. It makes 7 agents from various model families succeed more often, in fewer turns
🧵⬇️

Max Conti retweeted

Love the blog's title, nice wink at our work with @mlpc123 ! More importantly, I love the content ! Contextual embeddings is a super high potential direction with lots to do! Still waiting on 1M context window parallel embeddings though @antoine_chaffin @bo_wangbo 😘

We built a new way to train contextual embedding models, which encode each chunk of a document with the whole document in view.
pplx-embed-v2-context-9b-preview sets a new state of the art on ConTEB and @turbopuffer's new, privately held context-bench.
perplexity.ai/hub/blog/conte…

Max Conti retweeted

I will be in Seoul with @marcantallard this week for ICML to present ModernVBERT 🇰🇷
Our poster session on Wednesday from 10:30PM in Hall A (#4104). Come chat with us!


Max Conti retweeted

if you write some really good code these days everyone thinks you did it with Claude Code. if you lose a lot of weight everyone thinks you did it with Ozempic. at least you can still be really good at dancing. they don't make ozempic or Claude Code for being good at dancing
Max Conti retweeted

okay maybe it's a good time? We have a small colbert model trained at pplx, it is a continue-training of pplx-embed-0.6b, so native multilingual, just made it open and added a section how to use MaxSim kernel:
huggingface.co/perplexity-ai…


Releasing my first kernel on @huggingface:
MaxSim
Late-interaction retrieval (ColBERT / PyLate) bottlenecks on materializing the full similarity matrix. This kernel avoids it by using tiled scoring with simdgroup_matrix (Metal) and WMMA.
Result is 3–5× speedup compared to naive PyTorch.
Try it out 👇

Max Conti retweeted

We're releasing LateOn and DenseOn today. Two open retrieval models, 149M parameters each.
LateOn (ColBERT, multi-vector): 57.22 NDCG@10 on BEIR.
DenseOn (dense, single-vector): 56.20.
Both beat models up to 4× larger
We're open-sourcing the weights under Apache 2.0 🧵👇

Max Conti retweeted

The new generation of open state-of-the-art single and multi-vector retrieval models is here
It's time, DenseOn with the LateOn 🎶
@LightOnIO releases models that leap past existing ones, and everything you need to do the same!

Max Conti retweeted
Update on the Late-Interaction Workshop @ ECIR2026: it was amazing! 🇳🇱
So cool to meet late-interactors IRL for the first time, I enjoyed every bit of that day 🤗 And congrats & huge thanks to the organizers again.
Link to our work + poster below ⬇️


Max Conti retweeted
Great work from @weaviate_io that compares the performances of text retrievers and multimodal ones.
It appears that their errors are complementary, which makes their combination in hybrid search promising.
Check their paper!
arxiv.org/pdf/2602.17687

Most teams build RAG systems that only see text.
But a lot of queries 𝘳𝘦𝘲𝘶𝘪𝘳𝘦 visual understanding to answer correctly.
Most RAG systems treat PDFs the same way: OCR the text, chunk it, embed it, done. But that approach misses 𝗳𝗶𝗴𝘂𝗿𝗲𝘀, 𝘁𝗮𝗯𝗹𝗲𝘀, 𝘀𝗽𝗮𝘁𝗶𝗮𝗹 𝗹𝗮𝘆𝗼𝘂𝘁, 𝗮𝗻𝗱 𝘃𝗶𝘀𝘂𝗮𝗹 𝗿𝗲𝗹𝗮𝘁𝗶𝗼𝗻𝘀𝗵𝗶𝗽𝘀 that are a core part of the data.
My colleagues at @weaviate_io just published IRPAPERS, a benchmark that directly compares text-based vs. image-based retrieval over 3,230 pages from 166 scientific papers.
The setup is straightforward: take the same PDFs and process them two ways. For text-based retrieval, run OCR with GPT-4.1, then embed with Arctic 2.0 + BM25 hybrid search. For image-based retrieval, embed the raw page images with ColModernVBERT multi-vector embeddings. Then test both on 180 needle-in-haystack questions targeting specific methodological details.
Text-based retrieval edges out images at the top rank (46% vs 43% Recall@1), but images match or exceed text at deeper recall levels (93% vs 91% Recall@20).
But these two approaches fail on 𝘥𝘪𝘧𝘧𝘦𝘳𝘦𝘯𝘵 𝘲𝘶𝘦𝘳𝘪𝘦𝘴.
At Recall@1:
• 22 queries succeed with text but fail with images
• 18 queries succeed with images but fail with text
This complementarity is what makes 𝗠𝘂𝗹𝘁𝗶𝗺𝗼𝗱𝗮𝗹 𝗛𝘆𝗯𝗿𝗶𝗱 𝗦𝗲𝗮𝗿𝗰𝗵 so effective. By fusing scores from both text and image retrieval, they achieved 49% Recall@1 and 95% Recall@20 - beating either modality alone.
𝗧𝗵𝗶𝘀 𝗶𝘀𝗻'𝘁 𝗮 𝘀𝗶𝗺𝗽𝗹𝗲 "𝗶𝗺𝗮𝗴𝗲𝘀 𝘃𝘀 𝘁𝗲𝘅𝘁" 𝘀𝘁𝗼𝗿𝘆. Text-based retrieval provides stronger precision and works for most content. But image-based retrieval can use visual structure and handle abstract visualizations way better. This is why once again (multimodal) hybrid search beats out either option alone - getting you the best of both worlds.
The most promising direction seems like it might be agentic systems that dynamically weight text vs image signals based on query characteristics, to emphasize image retrieval when more visually grounded information is needed, and text when you need keyword precision.
Paper: 𝗮𝗿𝘅𝗶𝘃.𝗼𝗿𝗴/𝗮𝗯𝘀/𝟮𝟲𝟬𝟮.𝟭𝟳𝟲𝟴𝟳

Max Conti retweeted
Love this from @weaviate_io!

Multimodal Hybrid Search is one line of code in Weaviate (in the code golf sense⛳️)
Search with ColModernVBERT page image vectors, Arctic 2.0 text transcription vectors, and BM25!
This is an especially interesting case of a multimodal, multimodel 😆 future of search. Derive embeddings from images AND text (with two different models), and combine their retrieval scores. 🧬
What makes this possible at depth is that Weaviate's Named Vectors give you a lot of control over the underlying storage engine. In a naive case, you could have two HNSW indexes in-memory, with your metadata and inverted indexes handled with LSM buckets. 🏗️
Add MUVERA encoding with ColModernVBERT and Weaviate will now add an HNSW index with the FDE vectors in memory, and the full precision multi-vectors in an LSM bucket. 🪣
One object, one query. As many retrieval scores as you want 👇

Max Conti retweeted
Most practicionners would agree that text embeddings should be "contextual" - ie. they should encode a passage w.r.t. the wider scope of the entire document the passage stems from; "They beat the British" could refer to football or french history without further context...
In ConTEB (arxiv.org/abs/2505.24782), we highlight the standard failure modes of embedding models on retrieval tasks that require context to be properly embedded. We also propose a training strategy that extends standard "late chunking" to teach models to infuse embeddings with just the right amount of contextual knowledge to optimize retrieval.
Super happy to see some new work by @perplexity_ai on contextual embedding models. They eval on ConTEB and use our in-sequence contrastive loss, along with a ton of cool techniques in multiple phases of training. Love the work @bo_wangbo and will read in details, but super happy to see one more stone towards contextual embedding models, in the path already traveled by @hxiao and @jxmnop !
Link to the paper: arxiv.org/abs/2602.11151v1

Max Conti retweeted

Very proud of this paper, we lead many more experiments since the first release.
I think we made a pretty complete analysis of what is currently possible with the benchmark !
Thanks again to everyone involved !

Two months ago, we released ViDoRe V3 benchmark. Now, the full paper is out! 📄arxiv.org/abs/2601.08620
Here is a recap of the benchmark along with a comprehensive breakdown of our findings on multimodal RAG. 🧵 (1/N)

Max Conti retweeted
In our EMNLP 2025 Oral paper with @mlpc123, we propose an extension to Late Chunking and demonstrate how we can embed contextual information within passage embeddings... and why it's often very useful to improve document retrieval! (9/15)
arxiv.org/abs/2505.24782

Max Conti retweeted
🚨Should We Still Pretrain Encoders with Masked Language Modeling? We have recently seen massively trained causal decoders take the lead in embedding benchmarks, surpassing encoders w/ bidirectional attention. We revisit whether Bert-style encoders are a thing of the past? (1/N)

ALT Llama and Bert battling it out to determine what the best pretraining objective is - MLM or CLM ?
Max Conti retweeted
Dear Reviewer #2, the placeholder URL "hf.co / <anonymous_url>" does lead to a non-existent page as you so correctly note as the main paper weakness, but don't fret, you have everything zipped in the uploaded materials a few pixels down
