

Building iQonAi • Software, AI & Operations
Joined March 2010
- Tweets10.9K
- Following128
- Followers251
- Likes5.6K




the agents are starting to work on the infrastructure that runs them.
an orca session diagnosed a broken slack connector and opened a github issue.
another orca session running on devbox picked it up, handed execution to agent-task, and opened a PR with a proposed fix.
the pieces are starting to come together:
icarus defines the agents, tools, and permissions.
agent-task handles isolated execution
devbox is coming the control plane across hosts.
still early , but the pieces are starting to behave like a system.


18
the 1000x engineer isn't the one generating the most code. it's the one who knows which code shouldn't exist.

My “is engineering a valuable pursuit” math.
An outcome-oriented, creative engineer is now a 1000x engineer.
A tabs-vs-spaces-debating, miss-forest-for-trees engineer is now a -10x engineer.
The regular knowledge worker is now a 2x engineer.
This is also backed by the distribution of token consumption we see in both our startups and enterprise base. Engineers and software factories will consume exponentially more tokens.
If there’s a takeaway from Anthropic’s success, it’s that coding is the #1 killer app of AI.
19
i keep hearing that a memory layer isn’t a complete product.
i don’t necessarily disagree, but fragmented memory is probably my biggest frustration with AI tooling today.
i want to own where my memory lives and manage the distilled artifacts myself, not have everything locked away in separate providers.
the only time i’ve had anything close to shared context is with our internal tooling.
an open-source, self-hosted solution would be enough.
if that doesn’t exist, i might have to build it.
10
neon @ 2am: project is paused after reaching its monthly free plan limit. upgrade to resume.
orca: migrate us off neon free tier
prod app, real users, 12 seconds down. every table verified from bed at 2am.
it took longer to write this post than to migrate. what a time

1
24


Q. retweeted

You might want to make sure you have a few open-weight models backed up and some basic gear to run them. Who knows what really happened at NVIDIA, but the world just lost one of free AI's biggest proponents.

This interview by @pmarca explains what is really behind Jensen Huang's ouster as Nvidia CEO.

I feel like Steve Jobs, the customer doesn't know what they want. Almost always you have to show them what they need
1
66
this, but I want to own the memory layer

We decoupled memory from the model.
Living Brain is one persistent brain for ChatGPT, Claude, Cursor, Codex and your own agents. Write in one, retrieve in any.
92.2% on LoCoMo. 464ms median retrieval. Up to 22.6x fewer tokens per question.
LLMs have parameters. Living Brain has plasticity.
17

left arch as my daily driver for macOS
mbp m3 pro goes everywhere with me. had it for two years and it runs like a champ. everything heavy runs on two linux machines.
tailscale gets me into my old arch desktop, where i run claude sessions in tmux. from there, i can reach my home server, which manages the fleet of agents doing autonomous work.
most portable setup i've had. plenty of compute, without needing to reach for a hyperscaler
1
31
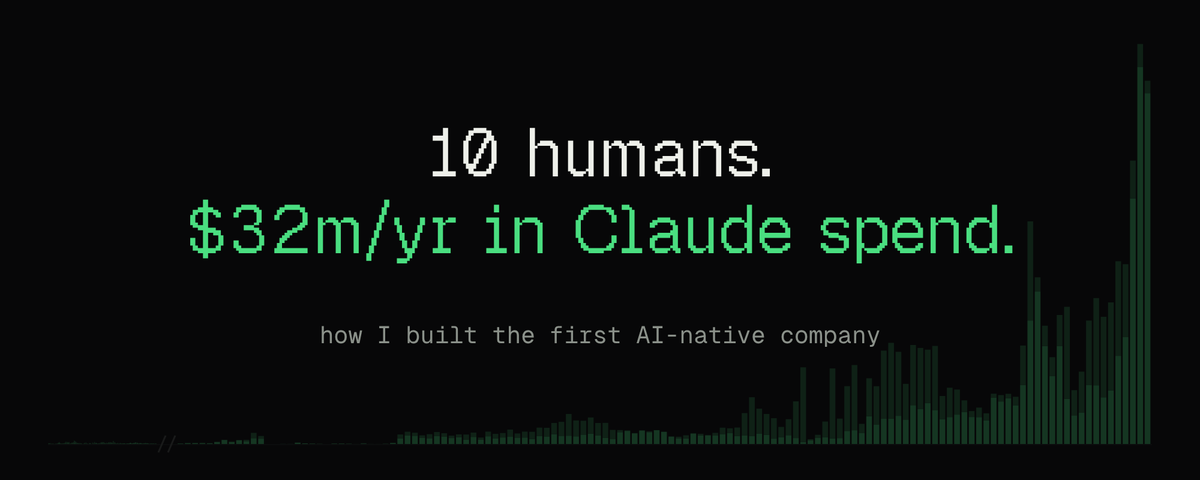
10 people, $32m a year in Claude spend, 77k PRs shipped in 30 days. a good read on how AI-native companies actually work

22
the main consumer of your API is an agent now. it doesn't need to be pretty, it needs nothing implied. explicit names, explicit errors, explicit defaults
we need APIs whose semantics are unambiguous to both humans and agents.
1
22
we don't need software engineers anymore. coding is dead. agents will do everything for us.
welcome to the age of autonomous attackers and defenders.
I'm sure not understanding computers will be just fine.
12
Q. retweeted

Gave an impromptu talk about PumaAI to a group of early stage founders, my friend recorded part of it ✨
We've been pretty quiet but tons to announce soon.
If you or your company cares about privacy in ai, please sign up here:
waitlist.pumaai.com 🐈⬛
opus 5.5 is smart but I'm smarter
mostly because I'm not transient. I retain context, pain, and the reasons behind decisions.
caught an agent PR today that worked, passed its tests, and still violated a contract I care about.
the code wasn't the problem. the judgement was

1
45

