
Chief Scientist | Committer of vLLM / LMCache / Production Stack
Joined January 2022
- Tweets127
- Following62
- Followers363
- Likes250




We posted our paper on how fast LLM prompt caching can wear out SSDs on arXiv.
Literally 6 hours later, another paper on the exact same topic dropped.
The competition is sooooo real 💀
Their paper (SARIA):
arxiv.org/abs/2610.31169
Our paper (Gandalf):
arxiv.org/abs/2610.30791
Kuntai Du retweeted

We teamed up with @IBM, @nvidia and @Supermicro to test whether KV cache needs to live in RAM, using LMCache to tier context to IBM Storage Scale.
na2.hubs.ly/H08ryQX0

Kuntai Du retweeted
Today we’ve announced to the world that 𝐓𝐞𝐧𝐬𝐨𝐫𝐦𝐞𝐬𝐡 𝐏𝐥𝐚𝐭𝐟𝐨𝐫𝐦, the 𝐦𝐚𝐧𝐚𝐠𝐞𝐦𝐞𝐧𝐭 𝐥𝐚𝐲𝐞𝐫 𝐟𝐨𝐫 𝐀𝐈 𝐢𝐧𝐟𝐞𝐫𝐞𝐧𝐜𝐞 𝐝𝐚𝐭𝐚, is officially live and enterprise-ready 🚀
Read the full announcement 👇
na2.hubs.ly/H08nsMN0
Kuntai Du retweeted
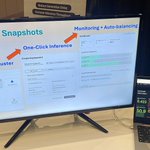
Day 1 of The AI Conference SF is in the books! 🎉 Come say hi to the team at Booth #214. We're excited to show how Tensormesh Platform can speed up AI inference and cut GPU costs with intelligent KV caching. See you on Day 2!
#TheAIConference #AIInfrastructure #LLMInference #KVCache


Interesting point:
Store LLM KV cache for days: store is cheaper
But store LLM KV cache for months: recompute is cheaper.
arxiv.org/abs/2505.07203

Predicted that LLM-as-a-classifier is a core workload one year ago.
One year after jev comes 😏
dl.acm.org/doi/abs/10.1145/3…

Besides just KV cache, what else can we do to make LLM agents faster?🧐
Check our (LMCache team) latest token dropping API! Dev-facing, easy-to-use. Drop half of tokens, ur LLM agent will then decode 1.6x faster!
Jupyter notebook example: github.com/LMCache/LMCache/b…
LMCache just hit 10,000 GitHub stars!🎉
2 years, we grow from a toy lab project to an open-source project used by industry and mentioned in NVIDIA GTC slides. As one of the early contributors and committers, here's my view of story 🧵

𝐋𝐌𝐂𝐚𝐜𝐡𝐞 𝐣𝐮𝐬𝐭 𝐡𝐢𝐭 𝟏𝟎,𝟎𝟎𝟎+ 𝐆𝐢𝐭𝐇𝐮𝐛 𝐬𝐭𝐚𝐫𝐬! ⭐
Thank you to every contributor, user, researcher, and engineer who has helped build, test, improve, and share LMCache. This milestone belongs to everyone who's been part of the community, and we're just getting started!
In just the past year, we've:
⚡ Shipped multiprocess (MP) mode, reducing time-to-first-token by up to 13× on MoE models by decoupling the KV cache from the inference engine
🔗 Introduced peer-to-peer KV cache transfer, enabling instances to fetch cached KV directly from one another instead of recomputing it
⚙️ Expanded inference engine support to TensorRT-LLM and SGLang
💾 Opened the storage adapter framework, making it easy to build and ship new storage backends without modifying the LMCache core
🖥️ Added multi-platform dev support, so you can build and test LMCache without needing a GPU
𝐑𝐞𝐚𝐝𝐲 𝐭𝐨 𝐡𝐞𝐥𝐩 𝐛𝐮𝐢𝐥𝐝 𝐰𝐡𝐚𝐭'𝐬 𝐧𝐞𝐱𝐭?
Whether you're looking for your first open-source contribution, already using LMCache, or interested in AI infrastructure, there are plenty of ways to get involved:
💬 Join our Slack → join.slack.com/t/lmcachework…
🛠️ Find an issue to work on → github.com/LMCache/LMCache/i…
🌐 Explore and star the project → github.com/LMCache/LMCache
Here's to the next 10K! 🎉
#LMCache #LLMInference #AIInfra #OpenSource #KVCache
Kuntai Du retweeted

I was delighted to give three keynotes recently, one at the 3rd HotInfra workshop at ISCA'26 (hosted by Prof. Jian Huang), one at the UIUC Systems Groups retreat (hosted by @tianyin_xu ), and a CMU guest lecture (hosted by Prof. Lei Li).
The message was simple: KV cache is BEYOND cacheable intermediate states.
It is what makes inference systems SMART.
- If cached, it saves cost and reduces latency.
- If analyzed, it reveals how the model attends to and understands context.
- If optimized, it can improve not only performance, but also output quality.
It's not a liability, but an ASSET --- (almost) always the more you have, the better.
That is the part most people in industry still underestimate, even though the techniques are already here today: KV cache compression, blending, semantic reuse, cross-model sharing, attention steering, KV-cache-based retrieval, and more.
The gap is not imagination. The gap is productization.
KV cache will become a core AI-native data layer in future inference infrastructure — not just something we store, but something we manage, analyze, and optimize.
#KVCache, #LMCache, #LLMInference, #Tensormesh, #vLLM, #SGLang, #MLSys, #HotInfra



Goblin is lowkey invading open-source projects lol.
GOBLIN MODE: ON
, ,
/(.-" "-.)\
|\ \/ \/ /|
| \ / =. .= \ / |
\( \ o\/o / ) /
\_, '-/ \-' ,_/
/ \__/ \
\ \__/\__/ /
___\ \| -- |/ /___
/` \ / `\
/ '----' \
[!] Goblin breach detected // LMCache docs
> Click to make them go away ▓▒░
docs.lmcache.ai/
massage and then cut, cruel

Cutting a sweet mango with machine
Readers added context they thought people might want to know
All mango varieties contain a large central seed or pit, which is absent in this video. mango.org/mango-facts en.wikipedia.org/wiki/Mango a-z-animals.com/blog/truth-or-…
So glad to see our project --- LMCache --- is included in the discussion!

llm-d published a new post on KServe + llm-d + vLLM for production LLM inference on Kubernetes.
Authors from @RedHat and Tesla describe how the stack addressed routing, customization, and day-2 operational challenges, citing 3x higher output tokens/s and 2x lower TTFT in one deployment after enabling prefix-cache aware routing.
By Yuan Tang, Scott Cabrinha, Robert Shaw, and Sai Krishna
@CloudNativeFdn
🔗 @_llm_d_ llm-d.ai/blog/production-gra…
#vLLM #KServe #Kubernetes #LLMOps #OpenSource


Key trick: don't use existing interactions directly ---- try to generate "lessons" from previous interactions instead.

ReasoningBank, a novel agent memory framework, enables LLM agents to continuously learn from both successful & failed experiences. Our evaluation shows that it enhances agent effectiveness, boosting success rates and efficiency. Learn more: goo.gle/4dWrPGb

ALT Workflow of ReasoningBank integrated with an agent during test time.
LLM providers start to take control...

A company with 60+ accounts just had its entire AI infrastructure taken offline by their provider.
No reason given, all that was provided was an appeal path as a Google Form.
This is not a one-off, we have mapped the pattern across every major closed-weight provider and what enterprise teams can do about it.
📖 Read the full blog: tensormesh.ai/blog-posts/ent…
🚀 Try Tensormesh with $100 in free GPU Credits: app.tensormesh.ai/login?logg…

My time being spent:
before using claude code --> write code
after using claude code --> read code, understand and find potential issues
My mental effort is not getting much lighter lol.

Heard that Qwen close-sourced their best model 😈

⚡ Meet Qwen3.6-35B-A3B:Now Open-Source!🚀🚀
A sparse MoE model, 35B total params, 3B active. Apache 2.0 license.
🔥 Agentic coding on par with models 10x its active size
📷 Strong multimodal perception and reasoning ability
🧠 Multimodal thinking + non-thinking modes
Efficient. Powerful. Versatile. Try it now👇
Blog:qwen.ai/blog?id=qwen3.6-35b-…
Qwen Studio:chat.qwen.ai
HuggingFace:huggingface.co/Qwen/Qwen3.6-…
ModelScope:modelscope.cn/models/Qwen/Qw…
API(‘Qwen3.6-Flash’ on Model Studio):Coming soon~ Stay tuned
