Junchen Jiang (@JunchenJiang) header
Junchen Jiang (@JunchenJiang) profile picture

CEO @Tensormesh, CS Prof @ UChicago https://teapawt.org/t.co/PIHealkTNi https://teapawt.org/t.co/hoetjwXKIt

Chicago, IL
Joined September 2012
Photo by Junchen Jiang (@JunchenJiang)Photo by Junchen Jiang (@JunchenJiang)Photo by Junchen Jiang (@JunchenJiang)Photo by Junchen Jiang (@JunchenJiang)Photo by Junchen Jiang (@JunchenJiang)Photo by Junchen Jiang (@JunchenJiang)Photo by Junchen Jiang (@JunchenJiang)Photo by Junchen Jiang (@JunchenJiang)
Junchen Jiang retweeted
Our first LMCache meetup in the San Francisco Bay Area was on 22 October 2026 at Samsung Semiconductor in San Jose, co-hosted by Dongjoo Seo of Samsung and Karsten Wade of Tensormesh. Samuel Shen of Tensormesh led a hands-on notebook session. Luis Chamberlain of Samsung spoke on asymmetric quantization, dma-buf with io_uring, and Cartridges. Dongjoo Seo closed with LMCache on CXL memory. If you missed it, the recap has all the slides and Sam's notebook, which runs LMCache on a laptop with no GPU. na2.hubs.ly/H08J0bq0
3
8
393
Junchen Jiang retweeted
inference engines should be bending over backwards more to get cache hits really interesting direction: > An Internet for the KV Cache - sending a KV cache across the Internet can now be faster and cheaper than computing it again.
19
16
4
314
26,495
Junchen Jiang retweeted
When is it better to fetch a KV cache than to recompute it? New on the LMCache blog: an Internet for the KV cache, by Siddhant Ray, adapted from his arXiv paper with Nick Feamster and Junchen Jiang of the University of Chicago. One example: DeepSeek-V4-Pro, about 100,000 tokens, about 1 GB of compressed KV cache. Sending it over a 10 Gbps link takes about 0.8 s and $0.09. Recomputing it on AWS 8×B200 takes about 15 s and $0.47. Under the post’s assumptions, transfer is about 19× faster and 5.2× cheaper ⚡ (AWS prices are examples only.) blog.lmcache.ai/en/2026/10/2…
12
13
6
140
9,660
Junchen Jiang retweeted
Today we’ve announced to the world that 𝐓𝐞𝐧𝐬𝐨𝐫𝐦𝐞𝐬𝐡 𝐏𝐥𝐚𝐭𝐟𝐨𝐫𝐦, the 𝐦𝐚𝐧𝐚𝐠𝐞𝐦𝐞𝐧𝐭 𝐥𝐚𝐲𝐞𝐫 𝐟𝐨𝐫 𝐀𝐈 𝐢𝐧𝐟𝐞𝐫𝐞𝐧𝐜𝐞 𝐝𝐚𝐭𝐚, is officially live and enterprise-ready 🚀 Read the full announcement 👇 na2.hubs.ly/H08nsMN0
4
1
12
279
Junchen Jiang retweeted
📅 New date: the LMCache hands-on workshop moves to Thursday 22 October. Same time, 1:30 to 5:30 PM Pacific. Same place, Samsung, 3655 N First St, San Jose. Still free, and registration is required. Four hours with a live LMCache environment, engineering sessions, and a reception to close. It falls during Open Source AI Week in the Bay Area. Bring a laptop for the hands-on part. Know someone who could not attend on 6 October? Send this to them. 🔁 na2.hubs.ly/H08k5bM0
1
3
185
Junchen Jiang retweeted
We're looking fsorward to being there. If you drop by our booth, we've got a snappy new LMCache ball cap for you. (And we'd love you to star our repo at github.com/LMCache/LMCache and follow us @LMCache!)
We’re proud to announce the first Partners & Exhibitors joining ODSC AI West 2026: @googlecloud | @Microsoft | @databricks | @intel | @qdrant_engine | Starburst | @runpod | Cranium | Sphinx | @datasaurai | @lmcache | Okareo | @senzing | @jetbrains | Merge Dev | Squadbase From cloud and data infrastructure to vector search, inference, AI security, evaluation, and developer tools, these teams are helping organizations move AI systems from experimentation into production. At ODSC AI West, you can explore their technologies, see practical solutions in action, ask technical questions, and connect directly with the people building the AI ecosystem. With 2,500+ AI builders and leaders gathering this October, the conversations shaping your next project, platform decision, or technical strategy could happen here. 🔥Last Chance -30% Off 👉 Register now: hubs.li/Q04zzvc90 📍 San Francisco 🗓️ October 27–29, 2026 | In-Person + Virtual #ODSCAI #AIWest #AIConference #AIInfrastructure #AIEngineering #DataScience #MachineLearning #AgenticAI
1
6
340
Junchen Jiang retweeted
𝑨𝑰 𝒄𝒐𝒔𝒕𝒔 𝒅𝒐𝒏'𝒕 𝒔𝒕𝒐𝒑 𝒂𝒕 𝒕𝒉𝒆 𝒕𝒐𝒌𝒆𝒏. As models consume more tokens to tackle increasingly complex tasks, the compute, memory, storage, and energy behind them matter too. AI economics and 𝒊𝒏𝒇𝒓𝒂𝒔𝒕𝒓𝒖𝒄𝒕𝒖𝒓𝒆 𝒆𝒇𝒇𝒊𝒄𝒊𝒆𝒏𝒄𝒚 are becoming the same conversation. ⬇️ na2.hubs.ly/H089px80
1
2
152
Junchen Jiang retweeted
Day 1 of The AI Conference SF is in the books! 🎉 Come say hi to the team at Booth #214. We're excited to show how Tensormesh Platform can speed up AI inference and cut GPU costs with intelligent KV caching. See you on Day 2! #TheAIConference #AIInfrastructure #LLMInference #KVCache
1
4
8
194
Junchen Jiang retweeted
The lmcache package on PyPI has passed 1,000,000 all-time downloads, per pepy.tech (CI traffic included). It stood at 1,002,795 on 2026-09-24. LMCache is an LLM serving engine extension that reduces time-to-first-token (TTFT) and increases throughput, especially in long-context scenarios. Current release: 0.5.5. Right now LMCache is a popular way to save money and reduce resource use for GPUs. If this doesn't matter to you directly, it probably matters to your customers. On GitHub, the project has 350+ contributors and about 11.9k stars. Thank you to everyone who has sent a pull request, reported an issue, or reviewed code. ⭐ github.com/LMCache/LMCache
3
1
6
429
Junchen Jiang retweeted
LMCache can now own an unmounted NVMe device as a KV cache tier: fixed-size slots, direct I/O, and checkpoints on the device, so the key index comes back after a crash. Dongjoo Seo, Ankit Kumar, Sangyoon Kwon, Daegyu Han, and Nayeon Kim of Samsung built Raw Block PR by PR. Their write-up also shows where it loses: when the page cache fits, buffered files can still win. So when is owning the device worth the alignment work? Before you try it, dedicate the device. Raw Block may overwrite what's there. blog.lmcache.ai/en/2026/09/2… #KV_cache #LMCache #Samsung #NVMe
5
1
16
868
🎉Exciting joint work between Amazon #SafeMaker and #LMCache!
Prefill and decode want opposite things from a GPU. Chunked prefill reduces the interference without removing it. On Amazon SageMaker HyperPod the two phases get separate GPU pools, and LMCache's PD backend moves the KV cache between them. Per-token latency then stops climbing with concurrency, where a colocated deployment degrades. Whether that pays off comes down to one question: can the KV cache move between pools faster than a decoder can recompute it? Xuan Lu, Vinay Arora, and Swapnil Palod at AWS, with Yihua Cheng at Tensormesh, measured it on Llama-3.3-70B-Instruct and wrote up the NIXL and EFA path that makes the answer yes. blog.lmcache.ai/en/2026/09/1…
1
10
949
Junchen Jiang retweeted
Our CTO @YihuaCheng is on the technical panel at AI Infra Signal, Sep 12th in Sunnyvale. Topic: the future of AI infra, from scaling models to operating agents. KV cache layout, eviction, compression, cross-node sharing, tiering to DRAM/NVMe. 100 spots, application-only. Apply: na2.hubs.ly/H07JLDG0
1
2
158
Junchen Jiang retweeted
🔬Calling ML engineers: turn your KV-cache editing idea into a real benchmark with LMCache! KV-cache techniques such as token dropping, KV cache editing, or even cartridge-style KV cache training allows an LLM to decode much faster or produce much better text outputs. But how to easily integrate them into a production-level stack and get real benchmarking numbers? Here comes the LMCache SDK! 💻 With the LMCache SDK, you can finish all your implementation with changing just ONE cell of a Jupyter Notebook, and get real throughput and accuracy numbers in a real inference engine! 🔥 Your KV-cache algorithm no longer has to stay inside a paper. blog.lmcache.ai/en/2026/09/0… Copy the notebook and try it out! colab.research.google.com/dr… Try the LMCache SDK: github.com/LMCache/LMCache/t…
4
1
12
953
Junchen Jiang retweeted
Tomorrow's LMCache Community Office Hour is an AMA. Karsten Wade (@quaid) has spent two months quietly reading the project — PRs, issues, Slack threads, plus an agentic scan. He'll share what he found, then answer anything you ask. Wed Sep 9, 11am PT lmcache-officehours.zapier.a…
1
2
250
Junchen Jiang retweeted
Kuntai Du is speaking at the @PyTorch Conference (Oct 20-21, San Jose) on scalable inference infra for agentic AI. We'll be there, come talk KV caching and vLLM serving with us. Register by 9/4: hubs.la/Q04tBgv_0 @this_will_echo
We’re bringing together open source leaders to tackle some of the biggest technical challenges in agentic AI at PyTorch Conference North America (Oct 20–21 in San Jose). Explore critical themes across the entire lifecycle, from adaptive post-deployment learning to vendor-neutral workload migration, scalable reinforcement learning infrastructure, high-throughput vLLM production serving and agent-assisted workflows for maintaining PyTorch itself. Featured Speakers include: @Google : Bill Jia @huggingface : Ben Burtenshaw, Sergio Paniego Blanco @IBM : Or Ozeri @intel : Eikan Wang, Huma Abidi @Meta : Yichuan Wang, Shuhua Yu, Felipe Mello, Jiani Wang, Edward Yang, Driss Guessous, Andrey Talman @adaption_ai : Sara Hooker @AgenticAIFdn : Mazin Gilbert, MBA, Ph.D. ByteDance: Neiwen LING @radixark : Mao Cheng @RedHat : Joseph Groenenboom, Tyler Michael Smith @tensormesh : Kuntai Du University of Virginia: Tianle Zhong Register for your standard ticket by September 4: hubs.la/Q04tBgv_0 + stay for AGNTCon + MCPCon that same week Read the Agentic AI and Next-Gen Sessions guide: pytorch.org/blog/agentic-ai-…
1
3
220
Junchen Jiang retweeted
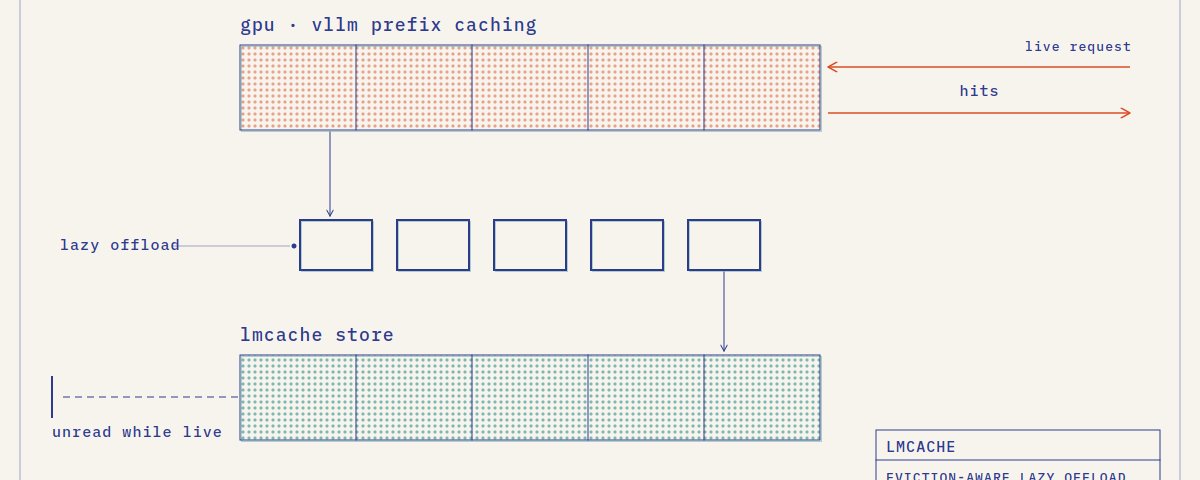
Your GPU is running out of room for everything it's supposed to remember. LLMs build a KV cache to avoid redoing work on repeated context. But GPU memory is scarce, and it's also holding weights and active requests. So where does that state live? GPU (fast, limited) Host memory Storage Or just recompute it No answer is automatically right. Each option trades off latency, capacity, and compute. We think KV-cache management deserves to be its own infrastructure layer, not something owned by a single worker.
1
4
224
Junchen Jiang retweeted
LLM KV caches taking up too much GPU space? 🤖 The LMCache Open Source community, lead by contributions from Dongjoo Seo and Jinyoung Moon at Samsung, just released support for Device-DAX! You can now use byte-addressable memory (like CXL) as a high-performance tier between DRAM and storage. Dive into the technical implementation, MP mode, and benchmarks here: Device-DAX in LMCache blog.lmcache.ai/en/2026/08/0… #LMCache #AI #CXL #KVcache #LLM #OpenSource
1
5
8
521
🎉 Great news for the #LMCache community! At FMS this week, EVERY vendor we saw was using LMCache to showcase their KV cache performance. That’s a testament to LMCache’s growing adoption, ease of use, and of course, performance, performance, performance. 🚀 #LMCache, #KVCache, #FMS
7
564
Junchen Jiang retweeted
𝗧𝗵𝗶𝘀 𝘄𝗲𝗲𝗸 𝗮𝘁 𝗙𝗠𝗦 𝟮𝟬𝟮𝟲 Our CTO, 𝗬𝗶𝗵𝘂𝗮 𝗖𝗵𝗲𝗻𝗴, will join the panel discussion, “𝗧𝗵𝗲 𝗙𝘂𝘁𝘂𝗿𝗲 𝗼𝗳 𝗞𝗩$,” alongside leaders from Dell, WEKA, and Samsung. As context windows grow and inference workloads scale, the KV cache is becoming one of the largest and most performance-critical working sets in modern AI systems. The panel will explore how KV cache capacity, bandwidth, tiering, offload, compression, sharing, and reliability increasingly shape latency, throughput, and infrastructure cost. Yihua will share Tensormesh’s perspective on the software and systems techniques needed to manage KV cache across GPUs, host memory, and storage, and where deeper co-design across the stack is still needed. 📷 Open-Source Software, Ballroom F 📷 August 6, 2026 📷 9:45 AM–10:50 AM 📷 Santa Clara Convention Center #FMS2026 #AIInfrastructure #KVCache #MemorySystems #Tensormesh
2
3
242