
Chief Scientist | Committer of vLLM / LMCache / Production Stack
Joined January 2022
- Tweets127
- Following62
- Followers363
- Likes250




Kuntai Du retweeted

We teamed up with @IBM, @nvidia and @Supermicro to test whether KV cache needs to live in RAM, using LMCache to tier context to IBM Storage Scale.
na2.hubs.ly/H08ryQX0

Kuntai Du retweeted
Today we’ve announced to the world that 𝐓𝐞𝐧𝐬𝐨𝐫𝐦𝐞𝐬𝐡 𝐏𝐥𝐚𝐭𝐟𝐨𝐫𝐦, the 𝐦𝐚𝐧𝐚𝐠𝐞𝐦𝐞𝐧𝐭 𝐥𝐚𝐲𝐞𝐫 𝐟𝐨𝐫 𝐀𝐈 𝐢𝐧𝐟𝐞𝐫𝐞𝐧𝐜𝐞 𝐝𝐚𝐭𝐚, is officially live and enterprise-ready 🚀
Read the full announcement 👇
na2.hubs.ly/H08nsMN0
Kuntai Du retweeted
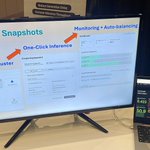
Day 1 of The AI Conference SF is in the books! 🎉 Come say hi to the team at Booth #214. We're excited to show how Tensormesh Platform can speed up AI inference and cut GPU costs with intelligent KV caching. See you on Day 2!
#TheAIConference #AIInfrastructure #LLMInference #KVCache


Kuntai Du retweeted

I was delighted to give three keynotes recently, one at the 3rd HotInfra workshop at ISCA'26 (hosted by Prof. Jian Huang), one at the UIUC Systems Groups retreat (hosted by @tianyin_xu ), and a CMU guest lecture (hosted by Prof. Lei Li).
The message was simple: KV cache is BEYOND cacheable intermediate states.
It is what makes inference systems SMART.
- If cached, it saves cost and reduces latency.
- If analyzed, it reveals how the model attends to and understands context.
- If optimized, it can improve not only performance, but also output quality.
It's not a liability, but an ASSET --- (almost) always the more you have, the better.
That is the part most people in industry still underestimate, even though the techniques are already here today: KV cache compression, blending, semantic reuse, cross-model sharing, attention steering, KV-cache-based retrieval, and more.
The gap is not imagination. The gap is productization.
KV cache will become a core AI-native data layer in future inference infrastructure — not just something we store, but something we manage, analyze, and optimize.
#KVCache, #LMCache, #LLMInference, #Tensormesh, #vLLM, #SGLang, #MLSys, #HotInfra


Kuntai Du retweeted

Why not store KV cache permanently?
In case you missed it, #IBM recently posted two blogs for 𝗹𝗹𝗺-𝗱 + 𝗞𝟴𝗦 + 𝗟𝗠𝗖𝗮𝗰𝗵𝗲-based KV storage. Thrilled to keep building together.
Avoiding recomputation is the goal, but it’s still rare to see KV cache treated as shared, persistent infrastructure in real production deployments.
Excited to see LMCache be part of this with IBM, a long-time collaborator of the LMCache community. Thrilled to keep building together.
These two posts are a great look at what that can actually look like in practice:
1. Rethinking LLM Inference Economics with llm-d, LMCache, and IBM Storage Scale
community.ibm.com/community/…
2. Deploying Distributed LLM Inference Service with IBM Storage Scale for KV Cache Offloading
community.ibm.com/community/…
Great read for anyone interested in fast yet cheap LLM inference.
#LMCache #vLLM #Kubernetes #K8s #KVCache

Kuntai Du retweeted
🔴 Live from #GTC2026
On the floor with our Chief Scientist @this_will_echo and CTO #Yihua Chang — #KVCache is the hottest topic of the day. Even Jensen opened with it.
🎙️They covered topics like:
#CacheBlend, @lmcache 0.4.0. and the super cool collab with @nvidia around a bot called #reachy using LMCache under the hood for 20x speedup
#GTC2026 #KVCache #LMCache #TensorMesh
Kuntai Du retweeted
🚀 LMCache has officially been out for 1.5 years now!
Within its success, LMCache has become the default KV-cache library for open-source LLM inference (CPU offload, P2P sharing, multi-backend storage, vLLM/SGLang integration, and more).
As a PyTorch Foundation Ecosystem project, LMCache is now used by enterprise leaders across the industry (GKE, AWS, Nvidia's Dynamo, llm-d…).
🤔What’s the secret to our product??
🔎 Come see yourself: arxiv.org/pdf/2510.09665
♥️ A huge thank you to our contributors and community, you’ve influenced what makes LMCache today. (@lmcache)
#KVCache #LMCache #LLM #vLLM

Kuntai Du retweeted

Meta just solved the biggest problem in RAG!
Most RAG systems waste your money. They retrieve 100 chunks when you only need 10. They force the LLM to process thousands of irrelevant tokens. You pay for compute you don't need.
Meta AI just solved this.
They built REFRAG, a new RAG approach that compresses and filters context before it hits the LLM. The results are insane:
- 30.85x faster time-to-first-token
- 16x larger context windows
- 2-4x fewer tokens processed
- Outperforms LLaMA on 16 RAG benchmarks
Here's what makes REFRAG different:
Traditional RAG dumps everything into the LLM. Every chunk. Every token. Even the irrelevant stuff.
REFRAG works at the embedding level instead:
↳ It compresses each chunk into a single embedding
↳ An RL-trained policy scores each chunk for relevance
↳ Only the best chunks get expanded and sent to the LLM
↳ The rest stay compressed or get filtered out entirely
The LLM only processes what matters.
The workflow is straightforward:
1. Encode your docs and store them in a vector database
2. When a query arrives, retrieve relevant chunks as usual
3. The RL policy evaluates compressed embeddings and picks the best ones
4. Selected chunks are expanded into full token embeddings
5. Rejected chunks stay as single compressed vectors
6. Everything goes to the LLM together
This means you can process 16x more context at 30x the speed with zero accuracy loss.
I have shared link to the paper in the next tweet!

Kuntai Du retweeted
Yesterday we hosted our first LMCache office hours! Jiayi Yao, Research Engineer at Tensormesh and one of the top contributors, covered LMCache architecture, key performance optimizations, and benchmark results-based on the newly published technical report available at arxiv.org/pdf/2510.09665. You can watch the recording here: youtu.be/y14ruG6CNGE?si=ktbf… Join us for the next LMCache office hours on December 11. Register to get it added to your calendar: lmcache-officehours.zapier.a…
Kuntai Du retweeted

Thanks to @github for spotlighting vLLM in the Octoverse 2025 report — one of the fastest-growing open-source AI projects this year.
🏆 Top OSS by contributors
🚀 Fastest-growing by contributors
🌱 Attracting the most first-time contributors
Trusted by leading open model communities and industry partners — including NVIDIA, Meta, Red Hat, DeepSeek, Qwen, Moonshot, and others — vLLM has become a preferred engine for efficient LLM inference.
With almost 63K stars and 1800 contributors, this growth belongs to the community.
Together, we’re building an easier, faster, and cheaper LLM serving for everyone.
👉gh.io/octoverse
#vLLM #OpenSource #AIInfra #Octoverse

Kuntai Du retweeted

🧑💻 gpt-oss-safeguard Hackathon 🧑💻
Join us Dec. 8 in SF for the Open Safeguard Hackathon — a collaborative event by OpenAI, ROOST & @HuggingFace to explore how open models can shape safer digital spaces and explore the future of open-weight reasoning and online safety.
Apply to participate: events.openai.com/gpt-oss-sa…
Kuntai Du retweeted
LMCache highlighted by CEO of Redis @rowantrollope at Redis Released SF 2025! 🎉
We’re thrilled to partner with Redis, bringing KV cache acceleration to the infra ecosystem.
#Redis #LMCache #AIInfra #LLM #Caching #SFTech #RedisReleased2025
📌 PS: Our team @kobe_eee(Kobe) & @this_will_echo(Kuntai) are here at the conference today—happy to connect in person if you’re around!


Kuntai Du retweeted
Good work and glad to see LMCache featured! 😀
Check out LMCache at github.com/LMCache/LMCache
Also we have our own K8s distributed inference framework, the vLLM Production Stack: github.com/vllm-project/prod…


LLM inference is too slow, too expensive, and too hard to scale.
🚨 Introducing llm-d, a Kubernetes-native distributed inference framework, to change that—using vLLM (@vllm_project), smart scheduling, and disaggregated compute.
Here’s how it works—and how you can use it today:
Kuntai Du retweeted
🚀𝗠𝗼𝗼𝗻𝗰𝗮𝗰𝗸𝗲 X 𝗟𝗠𝗖𝗮𝗰𝗵𝗲: KV Cache-centric Language Model Serving 🚀
We're thrilled to announce a strategic collaboration between LMCache and Mooncake to pioneer a KVCache-centric Large Language Model (LLM) serving system! This partnership is set to redefine efficiency, scalability, and responsiveness for LLM applications.
By uniting LMCache's cutting-edge KVCache management with Mooncake's robust and optimized backend infrastructure, we're unlocking new levels of performance for handling diverse LLM workloads. 𝗟𝗠𝗖𝗮𝗰𝗵𝗲 will serve as the 𝗰𝗼𝗻𝗻𝗲𝗰𝘁𝗼𝗿 between 𝗠𝗼𝗼𝗻𝗰𝗮𝗸𝗲 and 𝘃𝗟𝗟𝗠 to enable more cross-layer optimizations in LLM serving.
✨ 𝗪𝗵𝗮𝘁 𝘁𝗵𝗶𝘀 𝗺𝗲𝗮𝗻𝘀:
For LMCache users: Leverage Mooncake's advanced transfer engine and KVCache storage for significantly boosted data distribution and system performance.
For Mooncake users: Benefit from LMCache as the KVCache management layer, enabling flexible cache control and exciting future capabilities like CacheBlend.
📈 𝗣𝗿𝗼𝗼𝗳 𝗶𝗻 𝗣𝗲𝗿𝗳𝗼𝗿𝗺𝗮𝗻𝗰𝗲:
Our joint integration with vLLM (LMCache + Mooncake Store) has shown remarkable results on a Qwen2.5-72B-Instruct model (8xH800 GPUs):
⬇️ ~69% reduction in Average Time To First Token (TTFT)
⬆️ ~191% increase in Request Throughput
⬆️ ~185% increase in Output Token Throughput
...all thanks to efficient KVCache reuse!
For full results, please refer to our blog post: blog.lmcache.ai/2025-05-08-m…
🔮 𝗧𝗵𝗲 𝗙𝘂𝘁𝘂𝗿𝗲 𝗶𝘀 𝗕𝗿𝗶𝗴𝗵𝘁:
We're already collaborating on next-gen improvements, including optimized KVCache eviction/placement, asynchronous scheduling, zero-copy transfers, and more flexible caching strategies.
This is a significant step towards realizing the full potential of next-generation LLM serving architectures. Stay tuned for more updates!
𝗟𝗲𝗮𝗿𝗻 𝗠𝗼𝗿𝗲 & 𝗖𝗼𝗻𝗻𝗲𝗰𝘁: 👇
LMCache GitHub: github.com/LMCache/LMCache
Mooncake Github: github.com/kvcache-ai/Moonca…
vLLM Production Stack: github.com/vllm-project/prod…
LMCache Slack Space: join.slack.com/t/lmcachework…
#LLMs #AIServing #KVCache #OpenSource #TechCollaboration #LMCache #Mooncake #PerformanceOptimization #MachineLearning #AIInfrastructure #Innovation

Kuntai Du retweeted
🤯 78.8% p95 Inter-Token Latency reduction with LMCache + vLLM v1 P/D support 🚀
In our previous blog, we introduced the integration of 𝗟𝗠𝗖𝗮𝗰𝗵𝗲 with 𝘃𝗟𝗟𝗠 𝘃𝟭 and NVIDIA's 𝗡𝗜𝗫𝗟 library, enabling Prefill-Decode Disaggregation (PD) for LLM inference.
Today, we're thrilled to share the benchmark results that validate this integration achieves state-of-the-art PD performance. With this new integration, 𝗟𝗠𝗖𝗮𝗰𝗵𝗲 reduces p95 Inter-Token Latency (ITL) by 𝟳𝟴.𝟴%!! And the performance of distributed serving in vLLM v1 is now comparable and even lower than NVIDIA Dynamo in some cases!
For full result, please refer to our technical blog: blog.lmcache.ai/2025-04-29-p…
This achievement is the result of active collaboration with 𝗡𝗩𝗜𝗗𝗜𝗔 𝗗𝘆𝗻𝗮𝗺𝗼, leveraging insights from 𝗟𝗠𝗖𝗮𝗰𝗵𝗲 to push performance boundaries.
Introduction to Prefill-Decode (PD) Disaggregation
A leading solution for resolving the LLM inference problem is Prefill-Decode Disaggregation. The core idea? Separate the resource-intensive "prefill" stage (processing the input prompt) from the "decode" stage (generating subsequent tokens).
Without PD: New prefill requests can interrupt ongoing decode jobs, causing high tail latency for long outputs.
With PD: Dedicated decoders can stream tokens without interruption, ensuring a smooth user experience.
PD is rapidly becoming the default architecture in cutting-edge inference engines and production deployments.
This is precisely where LMCache comes in.
As announced in our previous blog, LMCache now provides the necessary integration with vLLM v1 and NVIDIA's NIXL to enable robust, disaggregated prefill.
Quickstart documentation: docs.lmcache.ai/getting_star…
LMCache + vLLM v1 + NIXL = PD at State-of-the-Art Speed
Final Notes
Disaggregated Prefill is rapidly becoming foundational for high-performance LLM inference. With LMCache's PD support for vLLM v1 + NIXL, we're bringing a robust, production-grade solution with state-of-the-art performance to the open-source community. We are proud of this step but believe there's always room for improvement. The LMCache Lab is collaborating closely with the vLLM team right now to explore even better designs for PD disaggregation.
Stay tuned – we're just getting started!
#LLM #AIOptimization #Inference #vLLM #LMCache #NVIDIA #NIXL #PrefillDecode #Performance #MachineLearning #DeepLearning #ArtificialIntelligence #MLOps

Kuntai Du retweeted
After feedback about our v0.8.4 benchmark for @deepseek_ai R1, we rerun it with suggested changes: vLLM no EP, SGLang updated v0.4.5 -> post1 and EP -> DP, TensorRT-LLM uses overlap scheduler and tuned parameters. We are seeing good results! So why was there a difference? 🧵

Kuntai Du retweeted
🚀 𝗧𝗲𝗻𝗰𝗲𝗻𝘁 x 𝗟𝗠𝗖𝗮𝗰𝗵𝗲 Collaboration: Integrating 𝗠𝗼𝗼𝗻𝗰𝗮𝗸𝗲 Store for Enhanced LLM Inference Caching! 🥮🥮
Excited to share insights from a powerful collaboration between Tencent engineers and the LMCache Lab team! 🎉
With the help from Tencent Engineers, we've successfully integrated high-performance Mooncake Store into the LMCache ecosystem via the new MooncakeStoreConnector. LMCache acts as intelligent caching middleware for LLM inference engines like vLLM, significantly reducing VRAM usage and compute overhead.
Our latest blog post dives deep into:
🔹 LMCache's architecture and the role of Remote Connectors.
🔹 A detailed look at the MooncakeStoreConnector implementation.
🔹 How this integration enables using Mooncake Store for KV cache offload & reuse in vLLM.
🔹 Guidance on extending LMCache with your own backend connectors.
This collaboration highlights the power of open-source synergy in tackling real-world production challenges for large language models.
Read the full technical breakdown here: blog.lmcache.ai/2025-04-22-t…
𝗟𝗲𝗮𝗿𝗻 𝗠𝗼𝗿𝗲 & 𝗖𝗼𝗻𝗻𝗲𝗰𝘁: 👇
LMCache GitHub: github.com/LMCache/LMCache
Chat with the Devs: forms.gle/hfcUeBV5pqgmEWWF6
LMCache Slack: join.slack.com/t/lmcachework…
vLLM Production-Stack Github: github.com/vllm-project/prod…
#AI #LLM #MachineLearning #Caching #DistributedSystems #OpenSource #Tencent #LMCache #vLLM #PerformanceOptimization #KVStore #MooncakeStore #Tencent

Kuntai Du retweeted
OpenRLHF is a pioneering framework to use vLLM for RLHF, driving many design and implementation of vLLM's features for RLHF, making vLLM a popular choice for many RLHF frameworks. Learn more about the story at blog.vllm.ai/2025/04/23/open…

Kuntai Du retweeted

Please stop attacking vLLM team’s integrity and being defensive about benchmarks involving SGLang. If you think the results are incorrect, please submit a PR to the open benchmark repo to correct the results.

I'm glad to see you've made some corrections. You can express humility by avoiding absolute statements like "We did not publish misleading results" or "We never misrepresent results."
How can you claim your previous results weren't misleading when your new TRT-LLM results are 2x faster on ShareGPT and 1.6x faster on 1k-in-2k-out compared to your previous TRT-LLM results? The same applies to SGLang.
Reproducibility and misleading results are distinct issues. One can produce reproducible yet misleading results by configuring an engine suboptimally, as you did in the previous post.
Everyone makes mistakes, and it's perfectly fine to acknowledge them rather than being defensive. I also find it challenging to benchmark these engines correctly due to their many advanced options.
This could become an endless battle, as engines improve daily, so I'd prefer to stop here and focus on real work.
See also:
teapawt.org/zhyncs42/status/191353…