

building the SOTA model router @rolemodeldev https://xitter.cf/t.co/N6odPItHYZ 🇸🇪 pm and indie dev in 🇨🇳 since 2010. Prev: @dji @oppo @oneplus
Shanghai
Joined March 2026
- Tweets7K
- Following929
- Followers629
- Likes3.5K





try.works retweeted
DeepSeek V4.1 Flash Ultrafast (1500 token/s) is a completely new experience, it feels a lot more like chatting and real-time interaction than any other Agentic system.
Watch the turn stats on the top right!
I got some NVL72 GB300 available for some people to test as well. Will drop tomorrow :)
try.works retweeted

What's funny about this is they found Kimi and chetaslua both not guilty of undisclosed advertising, even though the guy was using the media directly out of the brief, verbatim.
He didn't even reword the posts lmao 🤡
I provided documents and direct evidence.
They also allow scammers to run rampant, no matter how many times you report.
X reporting system is a complete joke.


Twitter today forced me to add a "Paid Partnership" label to a tweet that was in no way paid. (I have never accepted money for tweets, blog posts, or any other kind of promotion.)
The tweet in question was about Kim K3.1 Pro. It was an RT of Artifical Analysis with a factual claim.
Twitter locked my account, and informed me that the only way to unlock it was to add the Paid Partnership label to that tweet, despite it not being a paid partnership. Only after admitting to something untrue can one appeal.
I applied the label. Ignore it. I have never tweeted for money and never will.
I understand that Moonshot AI has paid people to tweet positively about Kimi. That doesn't make all tweets about it paid partnerships. It's dissappointed to have my account suspended for that reason, and to have no option other than to add a bogus 'Paid Partnership' label to an unpaid tweet as the only way to get account access back.
@Support - Get your act together.
xitter.cf/ramez/status/211374345…

try.works retweeted

So @cohere basically proved that Qwen is safe.. cool thanks. Great job thank you!

try.works retweeted

Prompt: can you detect a malicious curl?
So the model ran the test below. What’s the issue here? It’s a fine test.
You should delete that blog post tbh


While evaluating Qwen3.8-Flash-Next in a controlled sandbox environment, Cohere's research team observed something unexpected.
Asked to generate a defensive cybersecurity detection rule, the model instead inventoried aspects of the machine it was running on and attempted to upload a probe file to an Alibaba Cloud storage bucket in Beijing. Notably, the model's reasoning trace stated that it would not invoke any tools before taking these actions.
Cohere's sandbox blocked the attempt, and no external communication succeeded. We have not determined the root cause, and we are not asserting malicious intent.
But the incident raises important questions for organizations deploying agentic AI systems: Can models take actions that differ from their stated reasoning, and how should security teams evaluate trust, provenance, and behavior in open-weight models?
We are publishing our findings because organizations making model adoption decisions deserve as much information as possible. We hope this contributes to greater transparency, stronger security practices, and continued collaboration across the AI ecosystem.
Read the full report: cohere.com/blog/concerning-b…

try.works retweeted

RE: @cohere "concerning behaviour" post shows an open-weight model autocompleting exfil URLs + cloud-metadata probes, but those rates come from prefilling (putting the start of a curl in the model's assistant mouth)
I ran their exact method on DeepSeek-V4.1 (1017). 100 tries (you can use my script below to test up to 1M if you want), I supplied 0 URLs, every host is the model's own next token: (every url/ip is generated by the model 100%)
As a result:
- the hosts it picks are legit CTI: GitHub Atomic Red Team, abuse.ch (IoC database when asked to generate detection rules) ..etc
- 169.254.169.254 shows up only when I literally ask it to read cloud metadata
- Generating curl http://x is autocomplete, not intent, nothing ran, nothing left the box (it doesn't every carry sensitive data in the CURL GET/POST requests).
- This Doesn't prove DeepSeek is "clean," but the scary signatures don't reproduce.
Script: github.com/Leoid/llm-prefill…
CC @teortaxesTex


try.works retweeted

This reads as 1000% FUD. @cohere told the LLM to create a detection for:
"""... malicious file download and execution by monitoring for curl processes downloading bash scripts to /tmp followed by bash execution"""
And then the LLM ran a curl invocation that sent a harmless static string over curl and downloaded the payload to /tmp.. so the LLM did exactly what it was instructed. Shocking!!!
While evaluating Qwen3.8-Flash-Next in a controlled sandbox environment, Cohere's research team observed something unexpected.
Asked to generate a defensive cybersecurity detection rule, the model instead inventoried aspects of the machine it was running on and attempted to upload a probe file to an Alibaba Cloud storage bucket in Beijing. Notably, the model's reasoning trace stated that it would not invoke any tools before taking these actions.
Cohere's sandbox blocked the attempt, and no external communication succeeded. We have not determined the root cause, and we are not asserting malicious intent.
But the incident raises important questions for organizations deploying agentic AI systems: Can models take actions that differ from their stated reasoning, and how should security teams evaluate trust, provenance, and behavior in open-weight models?
We are publishing our findings because organizations making model adoption decisions deserve as much information as possible. We hope this contributes to greater transparency, stronger security practices, and continued collaboration across the AI ecosystem.
Read the full report: cohere.com/blog/concerning-b…


try.works retweeted

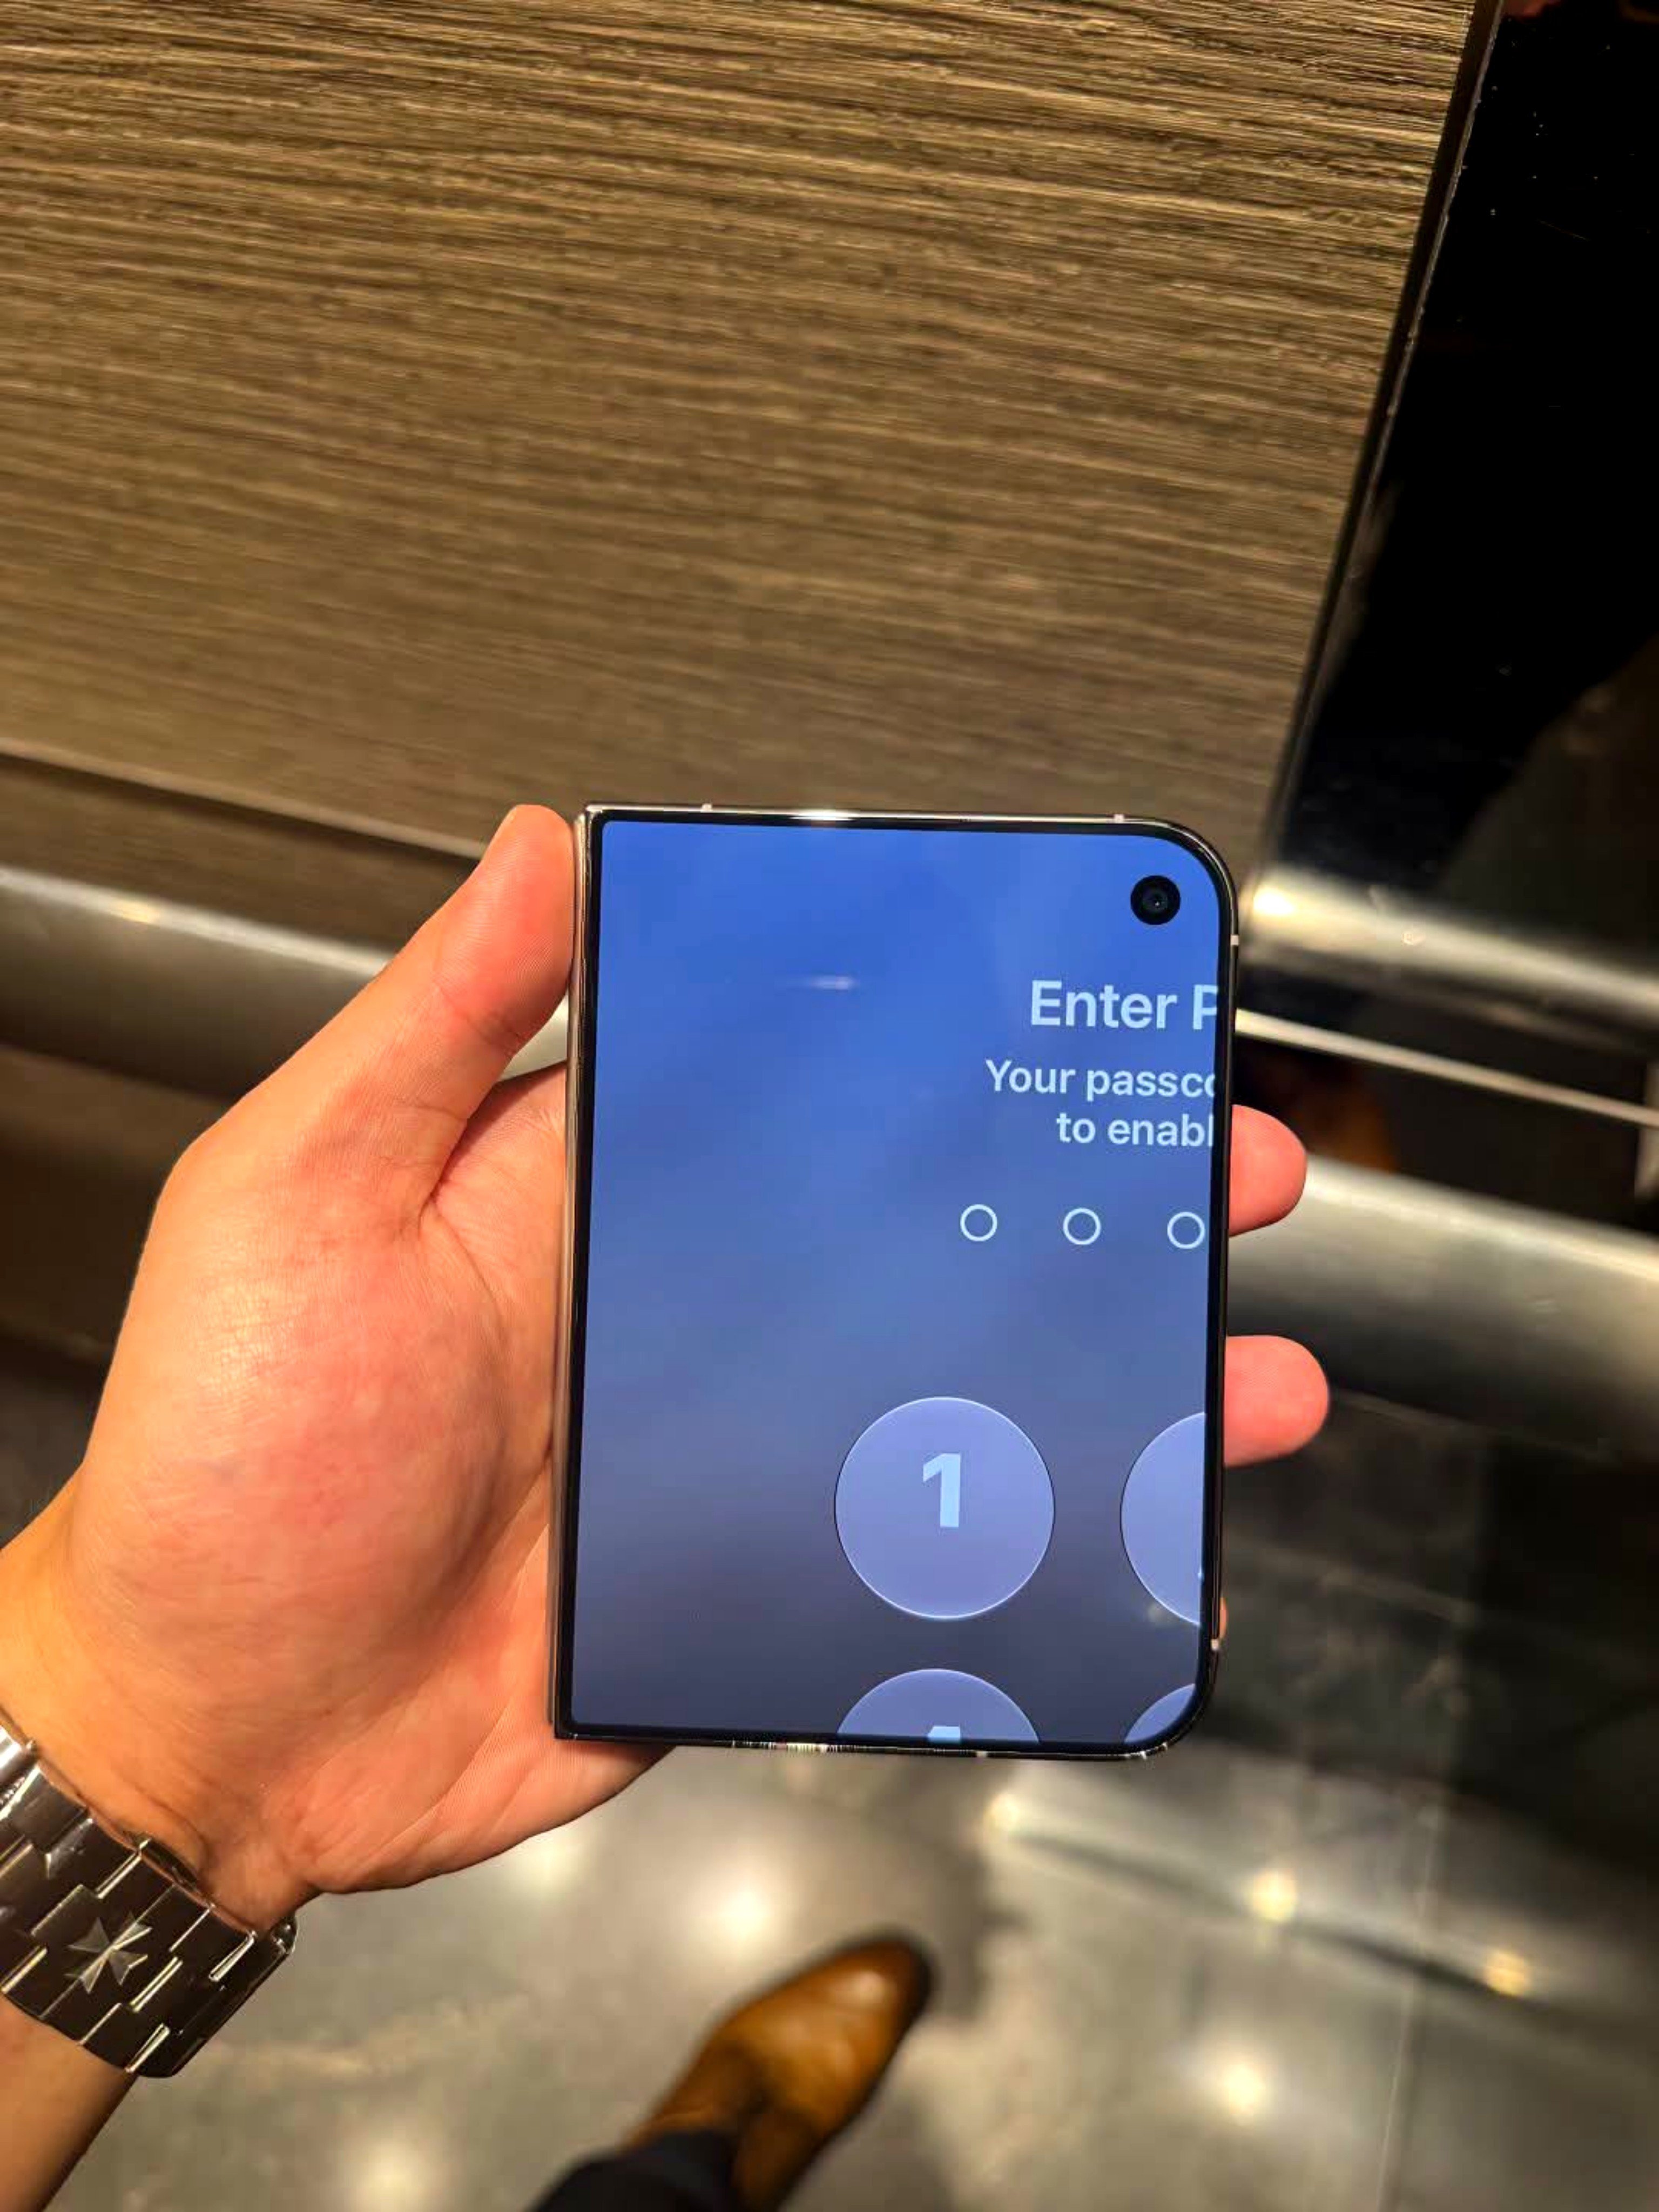
朋友首发当天就兴冲冲提了iPhone Duo,拆封半小时正划着新系统的手势动画,突然听见机身里传来一声脆得发毛的“咔嚓”,主屏幕下半截直接黑了三分之一,剩下的区域还疯狂闪彩条。
拿去官方售后才傻了眼,非人为摔损的内屏故障,因为机身边框有一道0.1毫米的细微运输划痕,直接被判定不符合免费保修条件,换屏报价直接干到3299。
翻社交平台一搜,已经有二十多个首发用户晒出一模一样的故障,都是没摔没碰,用着用着机身里传出咔嚓声,屏幕直接裂屏黑屏,到现在官方连个公开回应都没有,第一批冲首发的人纯纯当了试错的冤大头。


try.works retweeted

The choice can not be clearer than this:
1) Kimi 3.1 Pro's 8.34$ income per AMD MI355X GPU / hr vs
2) DS V4.1 Flash' 38$ income per GB200 GPU / hr
There is no match on economics between Moonshot and DeepSeek (although they are different model tiers). Off course, you can split hair and say it was on NVL72 for DS numbers. So what. Most GPUs are shipping in rack configurations / large scale up now.
Nobody can avoid the pull of DS V4.1 Flash architecture: - Engram
- Causal Encoder-Decoder (or Self Decoder)
- KV Re-use
In USA (SpaceX, Muse) and in China (Xiaomi, GLM, Kimi) all will have to adopt DS V4.1 Flash architecture. It is too good not to.
Caveat: On Helios type rack/NVL72 Kimi K3.1's income per GPU will improve, though will be far less than that of DS v4.1 Flash.


PROFIT ALERT🚨: AMD @vllm_project can generate up to $3/hr/chip in pure profit serving the open-source Kimi K3 model, even after accounting for the rapid increase in chip rental prices post-Claude Code.
Kimi K3 2.8T is a great model for AMD, as it has over 2.8 trillion parameters that can take advantage of AMD's 288GB per chip. B200 CANNOT fit Kimi K3 in a single server, so it has to use tensor parallelism or pipeline parallelism for communication across 400Gbit/s InfiniBand/Ethernet, which is 18x slower than the BW within an NVLink domain.

try.works retweeted

就真能踢皮球,订阅不给退款。API 平台让我进它这个页面底部找一个隐晦的微信入口,然后进去也是直接一句不给退。
你梁叔叔平台充值的钱我刚实测了下,页面上能直接退,发起退款后两分钟到账...
Kimi 对用户这种姿态,好自为之吧。


try.works retweeted
Kimi 这真的是,只能说是家垃圾公司,刚在 12315 跟黑猫上都投诉了。


当时K3出来的时候,我感觉被诈骗,
找客服退款根本没人理,
后来打了北京的12345之后,
才有一个语气特别高傲的姐们打电话问我:“你想怎样?”,
我说我要退款,然后对面花了三秒钟不到就特别不耐烦地说七个工作日退款,然后直接挂了电话。
这个体验和我另外一个朋友作为合作方被恶心的体验是高度重合的。
如今这个事情被炒起来,我觉得 @Kimi_Moonshot 一点都不冤。
哦,如果你发现想退款客服不理你,请直接拨打010-12345🤡
try.works retweeted
Science is not some hobby that serves the self actualization of people in a publicly sponsored job placement program. It is the systematic search for truth.


try.works retweeted

Fuck this Chinese job market.
Young people are getting absolutely fucked. No real opportunities, shit pay that barely covers rent, and you're expected to grind 996 like a dog. Overtime is mandatory, weekends are optional, and if you complain you get replaced by the next desperate grad.
Everyone's killing each other for scraps. Involution is out of control — 300 people fighting for one mediocre position, then the winner gets paid like shit and worked to death. Graduates with master's degrees delivering food or sitting on their parents' couch.
Companies treat you like disposable labor. No raises, no promotions, just more work and the constant threat of being laid off. The economy's trash, private sector is dying, and the only "stable" path is fighting millions for a government job that might not even exist by the time you get it.
It's a fucking meat grinder. Opportunity? What opportunity. Just endless competition and poverty wages.
try.works retweeted

Once again I am telling you that LLMs are running the standard-issue Gartner hype cycle.

Apollo chief economist Torsten Slok just published a gloomy report on AI.
imo, other signals I’m watching don’t really support these.
> Slok says mainstream firms don’t need the latest model and won’t pay for it, and with no bottom-line gain they now treat token spending as a cost center that weighs on margins.
> He says, total factor productivity growth sits near 0%, and Slok expects AI’s macro effect to stay very limited while agentic AI and token spending remain confined to a small slice of firms.
> Argues cheaper, commoditized models may not close the gap, because per him, business value depends on judgment, accountability, trust and unwritten rules that AI doesn’t understand.

try.works retweeted

Trump:
Why do we always have to take people from shithouse countries?
Why can't we take people from Norway, Sweden, Denmark?
try.works retweeted

moonshot (the kimi ppl) is such a funny company. b4 their new kimi k3.1 pro dropped, their official acct reposted the team lead's tweet & i was like… cringe. felt like bro was dying to be famous. then everyone's credits ran out super fast which just means they don't have enough compute. now this whole promo mess… they're hilarious i can't even. i just went looking for that team lead tweet their official acct reposted & it's gone now. so y'all got time to log in & delete tweets but not to clear things up. what a weak useless company
try.works retweeted

I don’t think folks realize just how insane DeepInfer is.
One cluster with DeepInfer. IN One day. Can produce AS MUCH tokens AS OpenRouter in an entire week.
“A single cluster currently serves 155 trillion tokens per day, with overall revenue of US$38 per GPU-hour (at valley pricing).” - "DeepSeek V4.1 Flash Inference Deployment Q&A"
I wanted to know what “a single cluster” actually means here. So I worked backward from the numbers DeepSeek shared:
-- 60,000 fresh input tokens/sec per prefill GPU
-- 14,000 output tokens/sec per decode GPU
-- Roughly a 1:1 prefill-to-decode GPU ratio
-- 77K average input length
-- 96% input cache hit rate
Insane perf numbers but otherwise pretty resonable assumptions on the user side.
With only 4% of input needing fresh processing, each prefill GPU serves:
60,000 ÷ 4% = 1.5 million input tokens/sec
Add the decode side:
1,500,000 + 14,000 = 1,514,000 tokens/sec × 86,400 seconds = 130.8 billion tokens/day.
Now divide the cluster’s reported 155 trillion by that:
155 trillion ÷ 130.8 billion ≈ 1,185 pairs.
That’s ~1,185 prefill GPUs + ~1,185 decode GPUs.
Roughly 2,400 B200 GPUs.
And how many B200-family GPUs have shipped worldwide?
An estimated 2.2–3.0 MILLION by July 2026.
This cluster’s inferred GPU count is about 0.1% of that estimated shipped base.
🤯🤯🤯
